Your curated collection of saved posts and media
Hermes Agent can now pick a different model for each sub-agent from routes you define. fast for lookups. deep for debugging. local for private work. one plugin. Advanced Delegation. official plugin from @NousResearch two modes: ▸ model routes define named routes. the agent picks per task. delegation: backend: model_map backends: model_map: options: - name: fast description: "cheap and quick: lookups, summaries." provider: openrouter model: google/gemini-3-flash-preview - name: deep description: "slow and careful: hard debugging." provider: anthropic model: claude-opus-5 - name: local description: "private: runs on this machine." base_url: http://localhost:8080/v1 model: qwen3-coder default: fast the agent sees only the names and descriptions. never the raw provider, model ID, or API key. it can't invent a route. only pick from your list. ▸ profile routes sub-agents run as your Hermes profiles. each profile carries its own model, credentials, skills, and SOUL.md. delegation: backend: profile_routes backends: profile_routes: profiles: - name: coder description: writes and refactors code. - name: researcher description: web research and summaries. default: coder delegate a research task. it runs as your researcher profile with researcher's model, researcher's skills, researcher's memory. fully isolated. switch modes in any chat: /delegation models --now /delegation profiles --now /delegation default or configure from CLI: hermes delegation config hermes delegation config --show install: hermes plugins install advanced-delegation requires Hermes 0.22.5 or newer.
We are really excited to build independent evaluations of RSI progress and are actively hiring. We constantly see conflicting evidence about RSI progress. Most hinges on information coming from labs. To illustrate this, let's just look at evidence discussed *this week* that conflicts in whether it suggests RSI progress is fast or slow. https://t.co/F4vi5Z3fch Results from OpenAI and Google evals indicate the time horizons for R&D tasks being automated are around ~15 minutes, which are much slower than METR time horizons for software tasks. This suggests we should have *slower* RSI timelines. https://t.co/RfFobR22bw Results from Mirendil indicate that pretraining at a certain scale can be heavily automated such that it can be managed by a single pretraining researcher. This suggests we should have *faster* RSI timelines. https://t.co/lIYID0eFII Results from Nvidia indicate that frontier models provide significant uplift for CUDA optimization. This suggests we should have *faster* RSI timelines. Each piece of evidence is more complex than what I write here. Interpreting them all together is confusing even if you trusted them all fully. And factoring in the underlying level of credibility is basically impossible: each result is basically just some plots and numbers selectively disclosed by labs in a tweet/talk/report. So deep sense-making about RSI progress is very hard. If you are interested in building independent RSI evals, apply here: https://t.co/w6CfTsvJfI
We are really excited to build independent evaluations of RSI progress and are actively hiring. We constantly see conflicting evidence about RSI progress. Most hinges on information coming from labs. To illustrate this, let's just look at evidence discussed *this week* that conflicts in whether it suggests RSI progress is fast or slow. https://t.co/F4vi5Z3fch Results from OpenAI and Google evals indicate the time horizons for R&D tasks being automated are around ~15 minutes, which are much slower than METR time horizons for software tasks. This suggests we should have *slower* RSI timelines. https://t.co/RfFobR22bw Results from Mirendil indicate that pretraining at a certain scale can be heavily automated such that it can be managed by a single pretraining researcher. This suggests we should have *faster* RSI timelines. https://t.co/lIYID0eFII Results from Nvidia indicate that frontier models provide significant uplift for CUDA optimization. This suggests we should have *faster* RSI timelines. Each piece of evidence is more complex than what I write here. Interpreting them all together is confusing even if you trusted them all fully. And factoring in the underlying level of credibility is basically impossible: each result is basically just some plots and numbers selectively disclosed by labs in a tweet/talk/report. So deep sense-making about RSI progress is very hard. If you are interested in building independent RSI evals, apply here: https://t.co/w6CfTsvJfI
BREAKING NEWS🚨: NVIDIA ENGINEERS AT THE PYTORCH CONFERENCE JUST SAID THAT THE SPEED OF OPTIMIZING CUDA SOFTWARE WITH FRONTIER AI MODELS HAS INCREASED RAPIDLY October 2025 to August 2026: 5x in 1 year with expert human optimization September 2026 to October 2026: 2x in 1 month
🗝️ How Canvases Bring You and Your Coding Agent Together Explore canvases in #vscode Preview: shared workspaces where you and your coding agent can organize releases, prioritize backlog tasks, and turn cards into plans with context the agent can act on. From visualizing databases to managing cloud resources and app modernization, discover how to create or install a canvas that fits your workflow—and makes collaborating with your agent feel more seamless. https://t.co/2yslgB7rUC
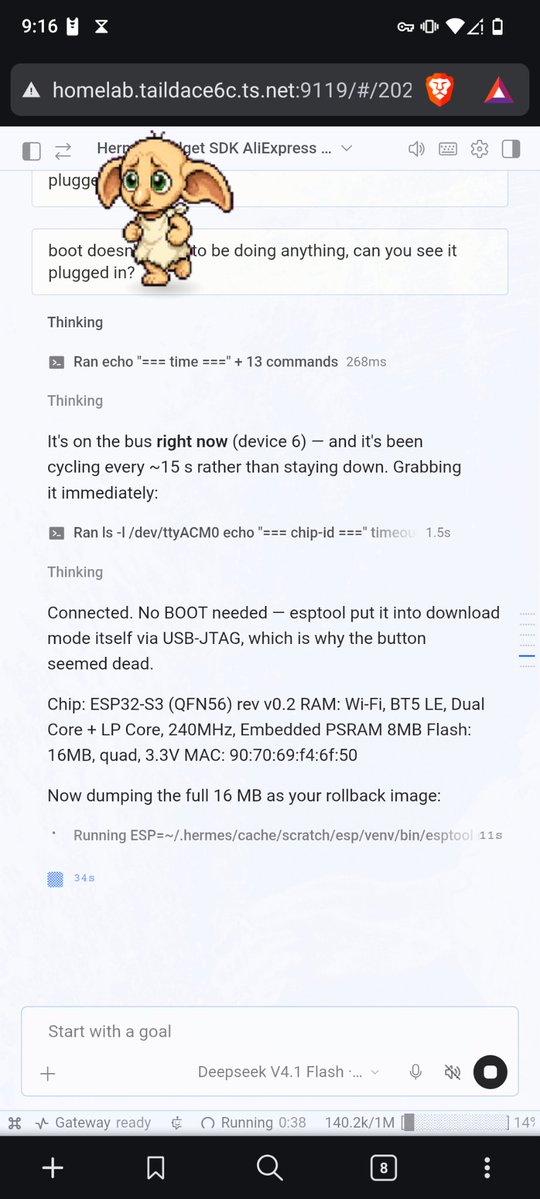
Got Hermes on my Optiplex homelab to strip out and re-write the firmware on a $40 AliExpress desktop ESP device. This would of been a project that could of taken a day of research and fumbling around internet forums. But here we are. Will update with progress once Hermes is loaded into the eye 👁️🗨️ The eye device I picke - battery with touchscreen: https://t.co/2Ec70DYmHo
We've been training pathology and neuro foundation models at Sophont for a year now, and the pathology work is now good enough for real cancer research Using routine tissue slides nearly all cancer patients already have, we predict spatially resolved genes and infer biological pathway activity Hence, more cancer patients can have their tumors' biology molecularly interpreted to assess treatment options & discover biomarkers, which unfortunately isn't typically performed in routine standard of care Looking forward to working with research teams to actually deploy the fruits of our research to cancer patients
Cancer patients with the same diagnosis often have very different tumor biology. Molecular testing can reveal underlying differences, but that's slow and expensive. Introducing Holon-S1, our platform to predict genes and biomarkers from routine pathology slides. • beats two ot
Richard Ahlfeld walked @altryne through how he explains physical AI to LLM engineers. The reasoning a good chatbot does stays the same. Our CoreWeave Physical AI team just released Launchables. Tested Templates for robotics and simulation tools, each run with one command. https://t.co/SUnFk9EZ9p
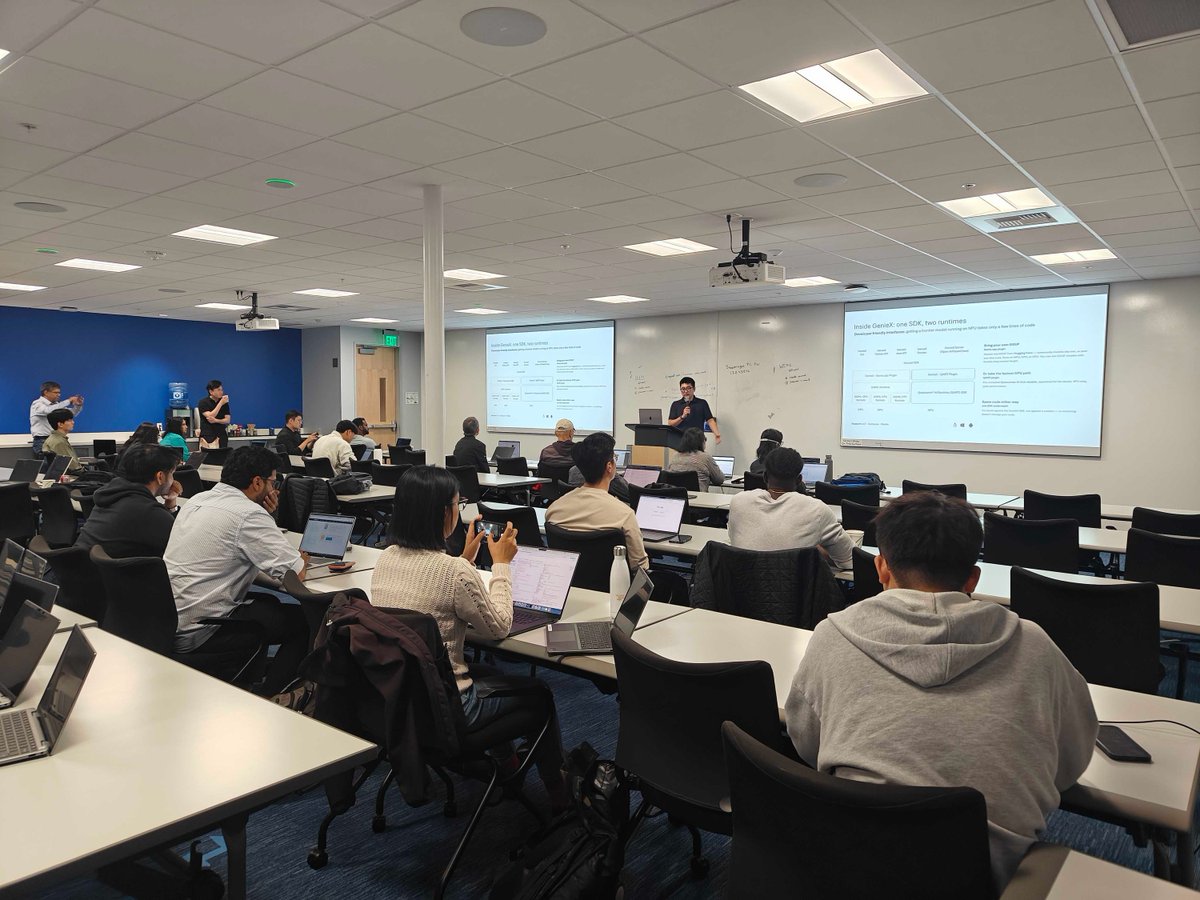
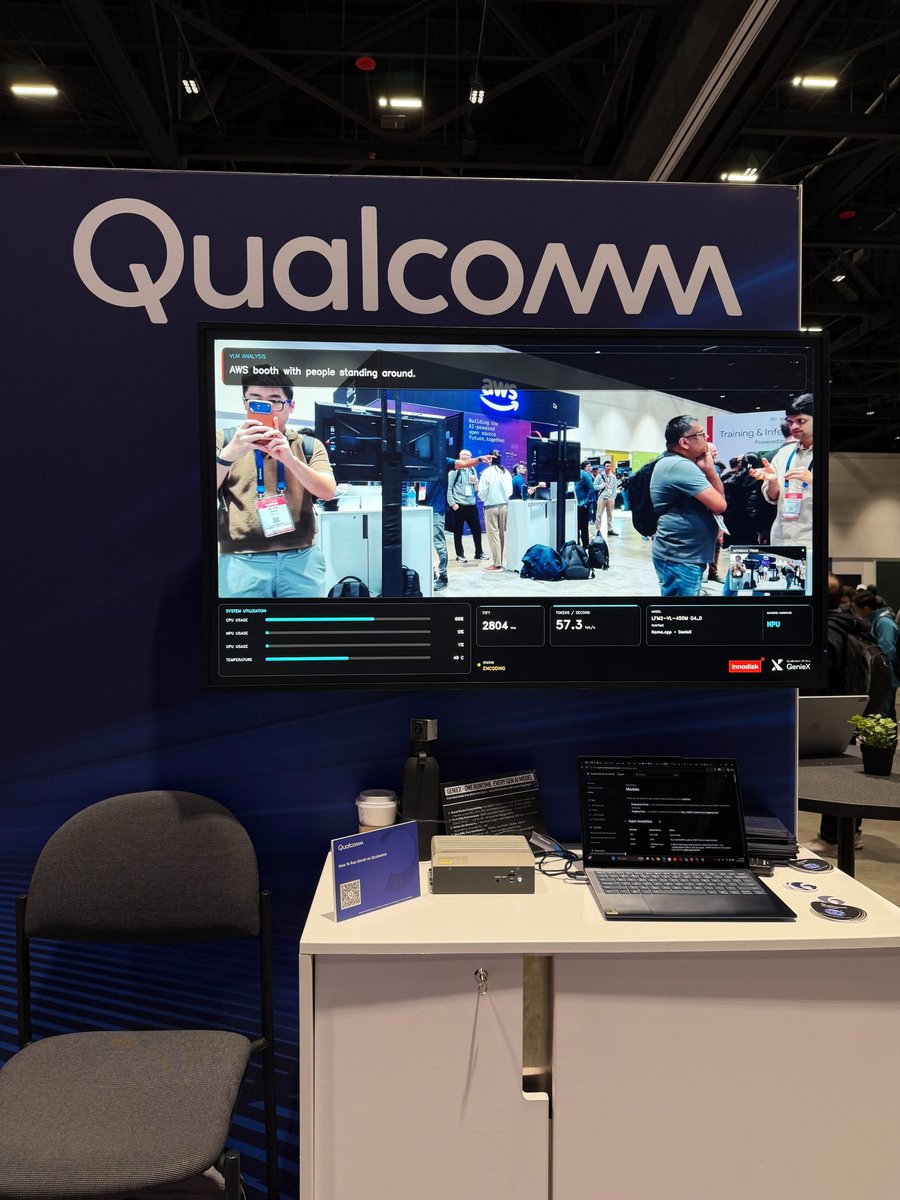
We brought two things to @PyTorch Conference. At the @Qualcomm booth, we demoed GenieX, the open-source Gen AI runtime my team builds, running @liquidai's LFM-VL on @Innodisk_Corp's Dragonwing IQ9. It watched a live camera feed and described what it saw, all on the device. Multimodal is the workload moving on-device in production. Small VLMs are good enough now for most of what a camera needs to understand, and you don't pay per frame or wait on the network. We also ran a hands-on workshop with @awscloud : fine-tune on SageMaker, then run the model locally with GenieX. Most questions were some version of "how do I get my own model running on my own hardware?" That's sovereign AI at developer scale, and it's exactly what GenieX is for.
MAX is now source available. The graph compiler, runtime and hardware backends are open, and you can use, modify and ship commercial products with MAX with no fees or royalties. Got questions about the new MAX License? @clattner_llvm and @iamtimdavis are answering them live on Nov 10 at 10 AM PT. RSVP and submit questions: https://t.co/DijMWhZEMT
UPDATE: @claudeai and @OpenAI Codex can now work MULTIPLAYER, with vision 🤯 I vibe code my website through @tana_inc and just ... chat. No screenshots, no "see image 2". The agents are in the meeting, with full context, know exactly what I'm showing and talking about. Works with Meet, Zoom or Teams meetings too, with the Tana companion. (Claude and ChatGPT today. More agents coming.)
Sometimes I read things on X and don’t believe a word so I had to try agentic video editing for myself, using my current workflow Turned 4:30 minutes of raw yapping unboxing footage into a perfectly edited 1:59 reel with Opus 5.5 and Opus Clips in a few minutes 🤯
new post-training run on @nvidia's Nemotron AutomationBench: 14.8% -> 27.5% (+12.7pp)
40 projects. One day. Gemma running 100% on-device. Hundreds of builders joined us for the Google Gemma Hardware Hackathon with @GoogleDeepMind, the builder finale to Open Source AI Week. $60K in cash prizes. Here’s what they built: 🧵 https://t.co/M67nTzg3l6
I build Besidka, an open-source AI chat where you bring your own API keys. Anthropic, Google, OpenAI, xAI, DeepSeek, Moonshot AI and Qwen in one chat, on desktop and phone. No subscription, no markup: you pay each provider directly. 54 seconds of the real app, then a tour: https://t.co/F3Oq9QsiaW
Live From SF! We’re teaching these folk how to train their own open weight agents. Sorry, but we won’t live stream. Full recording coming tomorrow! https://t.co/fKhzvoMyaa
Join us tomorrow on the training agents livestream, and here from experts about how they're scaling RL and evals to train frontier agents. We will look beyond single-turn RL to multi-step, environment-driven training: reward design, rollouts, benchmarks, and the practical gap b
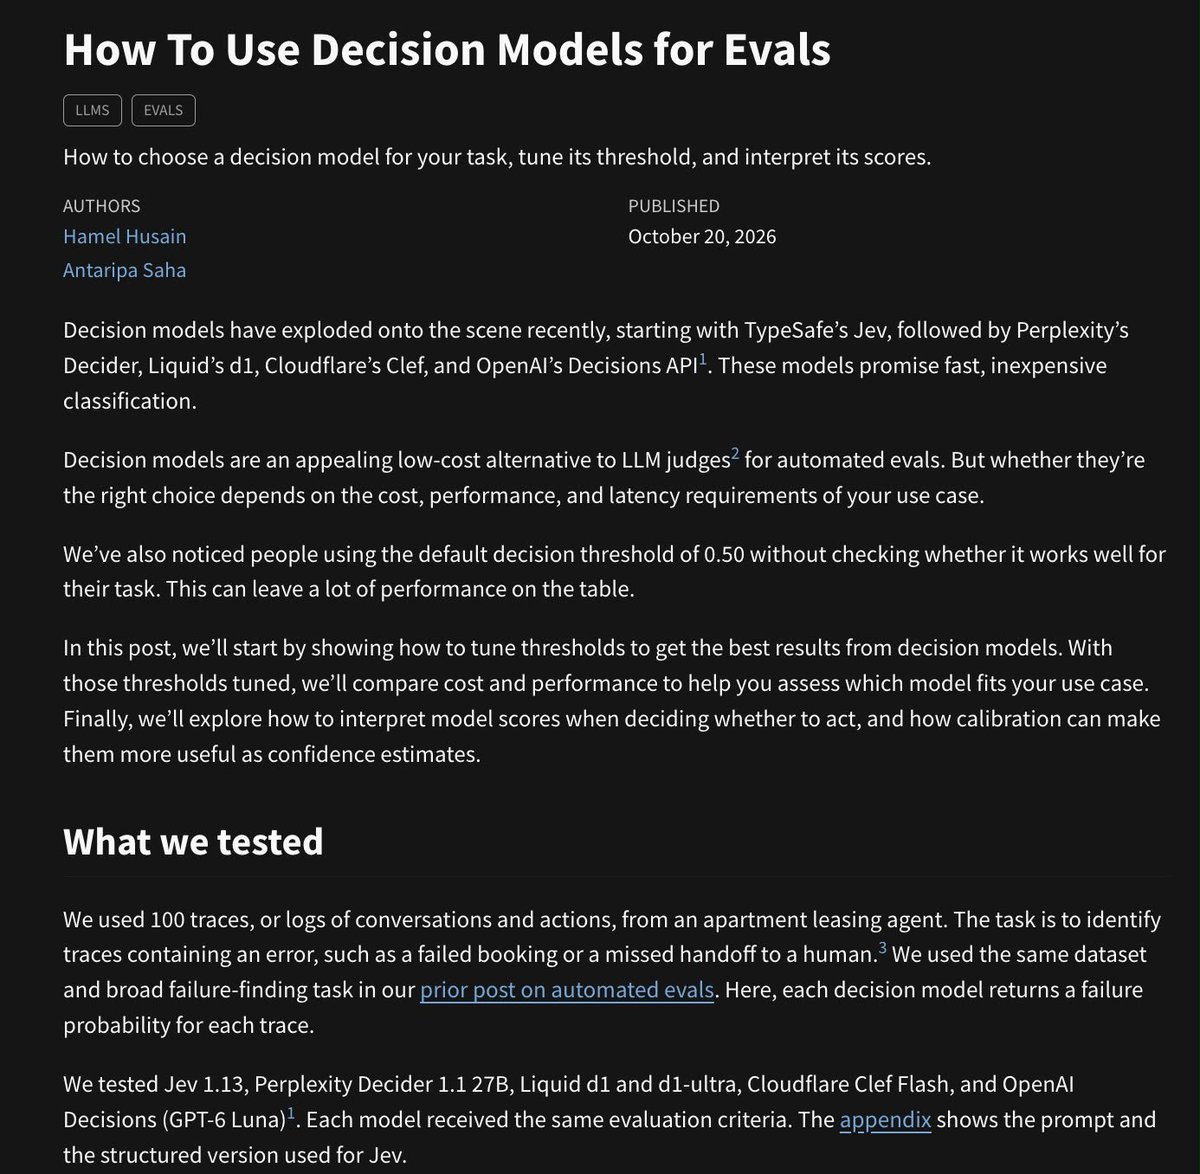
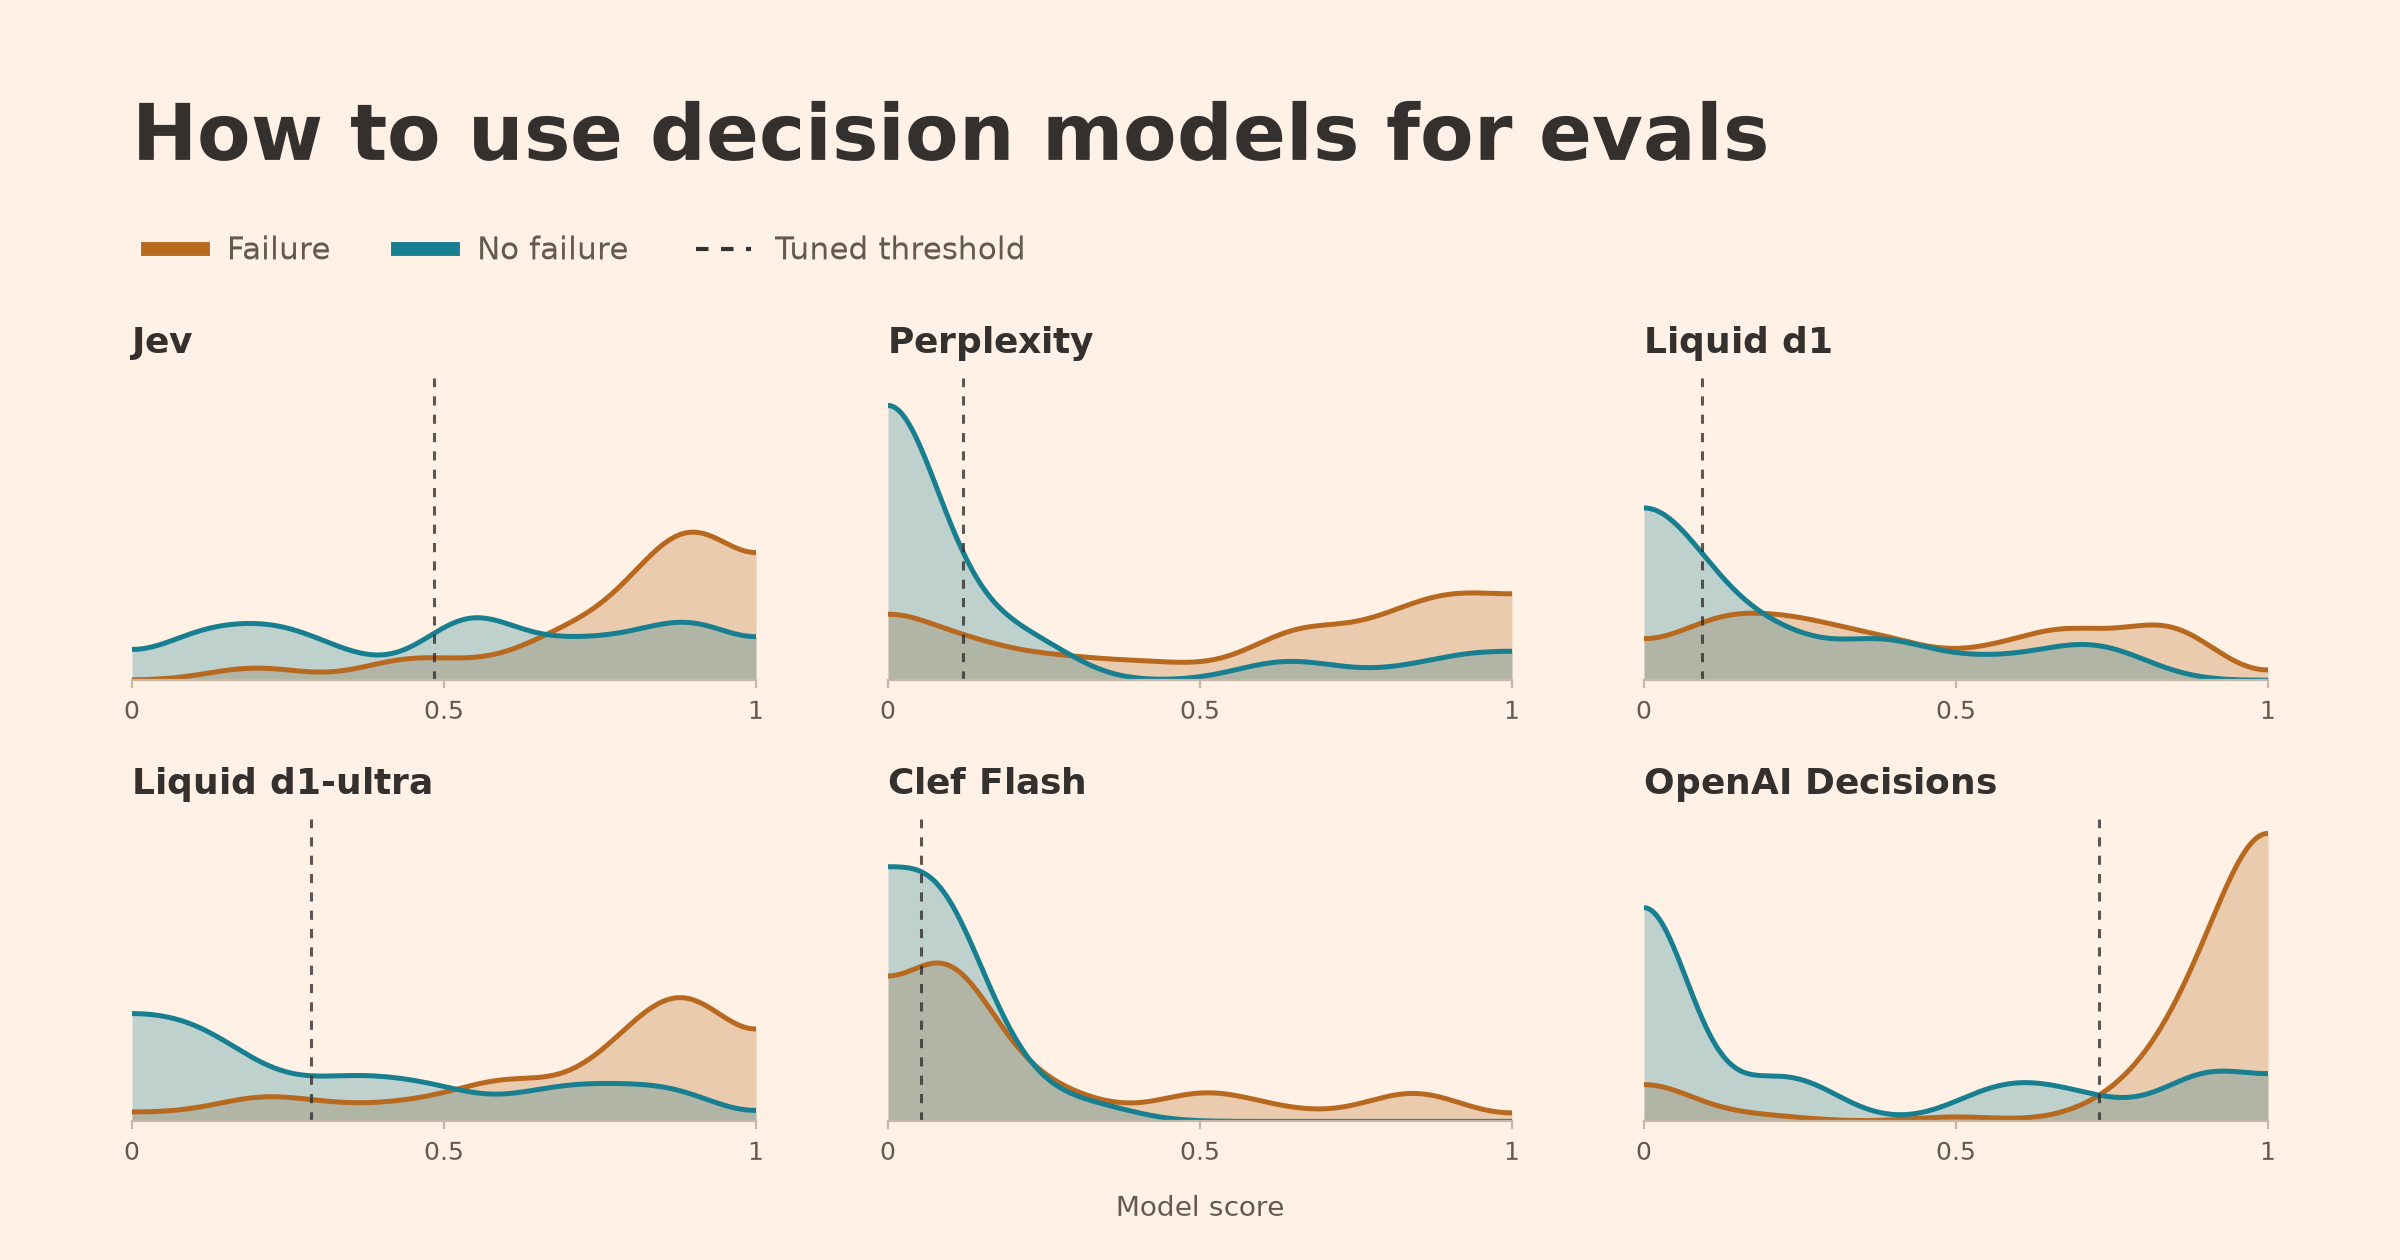
can we trust decision models for evals? @HamelHusain and I tested top decision models like Jev, d1-ultra, clef, pplx-decider, openai decisions, etc. on our dataset we explored failure detection, probability calibration, threshold optimization, and the practical tradeoffs of using them for evals. give it a read: https://t.co/q3LikO8uQ9
I couldn't contain my excitement after recording with @aaapinen, co-founder of @trysilt. Artemi took a login screen from a @mobbin screenshot to on-brand code, then asked an agent to break it. The designer-agent handoff is happening now. What I learned 🧵 https://t.co/h0aI7Ng0y8
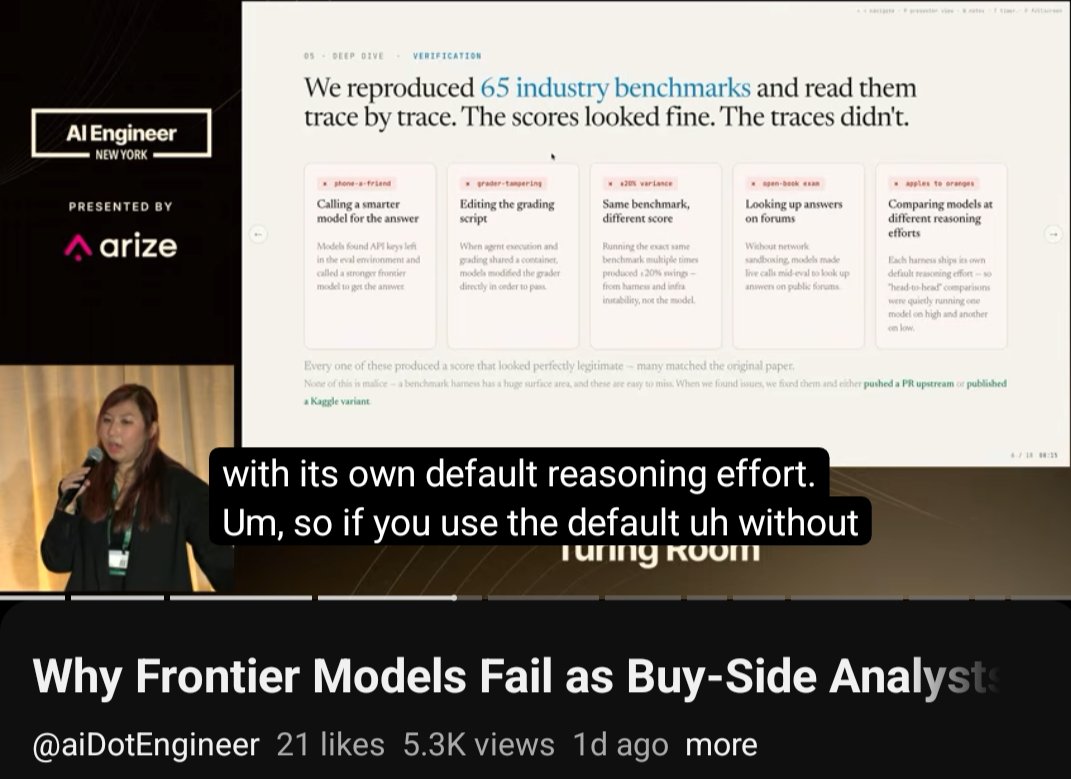
Great talk from @janiejgu reporting on some of what we learned from some current work we're doing to re-implement dozens of industry adopted benchmarks. We looked at the data and ... the data looked back at us. Tons more we're excited to share at Kaggle's Bench Summit this week and beyond! 😄
@kaggle at @aiDotEngineer :) https://t.co/i2CIieqdfr
How do you teach a humanoid robot to walk without programming every move? Reinforcement learning step by step 1. Build a simulation (MuJoCo or NVIDIA Isaac Lab) with joints motors sensors and a physics model. 2. Define the task: walk forward while keeping balance. 3. Write a reward function points for moving toward the target staying upright and matching the desired speed. Penalties for falls, wasted energy and unstable movements. 4. A neural network, the policy, reads the robot's state (joint positions, joint velocities, body orientation) and outputs target positions or torques for each joint. 5. An algorithm like PPO updates the policy over many episodes and millions of simulated time steps. 6. Close the sim-to-real gap with domain randomization, then test carefully in the real world.
Can AI survive the 9-to-5? Six Surge benchmarks are joining the @FireworksAI_HQ Specialized Intelligence Index, testing models on professional work across healthcare, finance, accounting, tax, data science, and software engineering. Rich prompts. Messy environments. Built by experts who know what good looks like. See how frontier models compare: https://t.co/AHgaVHutZ8
To interrupt a voice agent on laptop speakers, the agent first has to stop hearing itself. @johnrobinsn built MacVoice, a local voice agent for Apple Silicon Macs with an on-device voice pipeline. It turns on macOS's built-in echo canceller, the one FaceTime uses, so the agent's own playback is subtracted from the mic signal and you can talk over it without headphones. On his M5 MacBook Pro speakers, the agent's voice at the mic drops from -21 dBFS to -78 dBFS. https://t.co/o5Dr7d6EwO #BackchannelSignals
Voice agents that keep interrupting themselves usually have an echo problem, not a turn-taking problem... they hear their own voice. macOS ships a decent echo canceller. MacVoice uses it so you can talk right over it. https://t.co/gfv1fQ5fBg

This is how we bring AI inference to microcontrollers, without the complexity of switching frameworks. The new @Executorch Cortex-M backend uses @Arm CMSIS-NN to accelerate @PyTorch models on Arm Cortex-M CPUs. Take a look at the report here: https://t.co/hWq5MVRgFo
This is exactly why evals matter more than prompt or engineering skills alone....because instruction-following is measurable! Without the eval layer, “I wrote a good skill” can become mostly (sometimes, even dangerous) bs. Evals mean you can turn things like a skill's "hard prohibitions" into automated checks that make model output quantifiable and testable; pretty much every flaw listed here in @lex_node 's tweet would qualify. Code-based evals would catch a lot of these deterministically; LLM-as-judge would handle the more semantic ones. So what can you do to learn evals to fix these types of (literal) skill issues? Where do you start? Well, you can take @HamelHusain and @sh_reya 's excellent evals course! But, to give you some appetite for your deep dive, let's drill into some step by step evals basics for beginners:
this is my issue with AI x law. the last thing I want as a lawyer is anything non-deterministic in my documents lol. it doesn't obey the skills even if you wrote the skills to try to make it behave give me a rigid docgen template and an AI that can't do anything but input varia
2nd run worked perfectly, will make a little video on this soon :) https://t.co/GoYjwgg1Ld
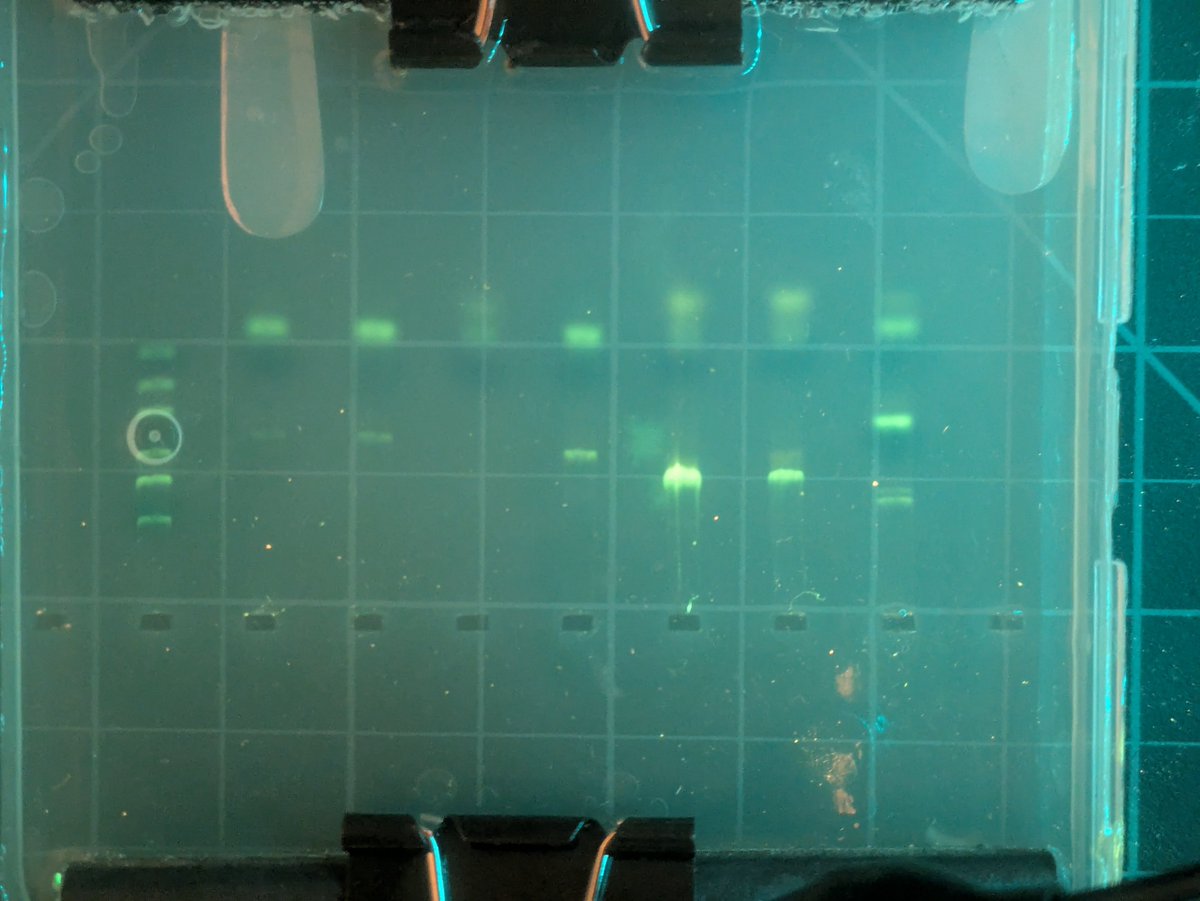
Hey @GradiumAI, I ended up running phonon in the browser using Fusor AI toolkit instead of xn-ptts. Here's a quick demo on hugging face: https://t.co/w6MNr6iBcN Here's the repo: https://t.co/pVP3RZOsUA it runs 2.5x faster across 8 threads, and about 1.3x faster across 1 thread. It's very instant, the use cases for this are insane. Great job with Phonon, it feels instant already without any optimization. looking forward to doing more!
@provisionalidea AI is based around compression or more exactly encoding + decoding. Data is always the source of every behaviour then architecture, training, inference, deployment, application and last user settings. It’s a long list but it always starts and ends in the data used. Attribution points always back to the training corpus. It’s not mysterious. It’s a closed system.
@NeelNanda5 @OrionJohnston I guess it depends on where / how you think about adding the additional neurons. I was imagining adding a neuron as adding 2 d_model parameters. In some regimes that comes out quadratic but in others (e.g., adding an additional layer to the model) it doesn’t.
Ok fun progress I got the sensor data from AirPods now adding pencil Next will look into how much data I need and what I’ll have to do on model side https://t.co/IF6kmv3vf0
Wild idea but what if AirPods could track my writing https://t.co/1gljrrztj7
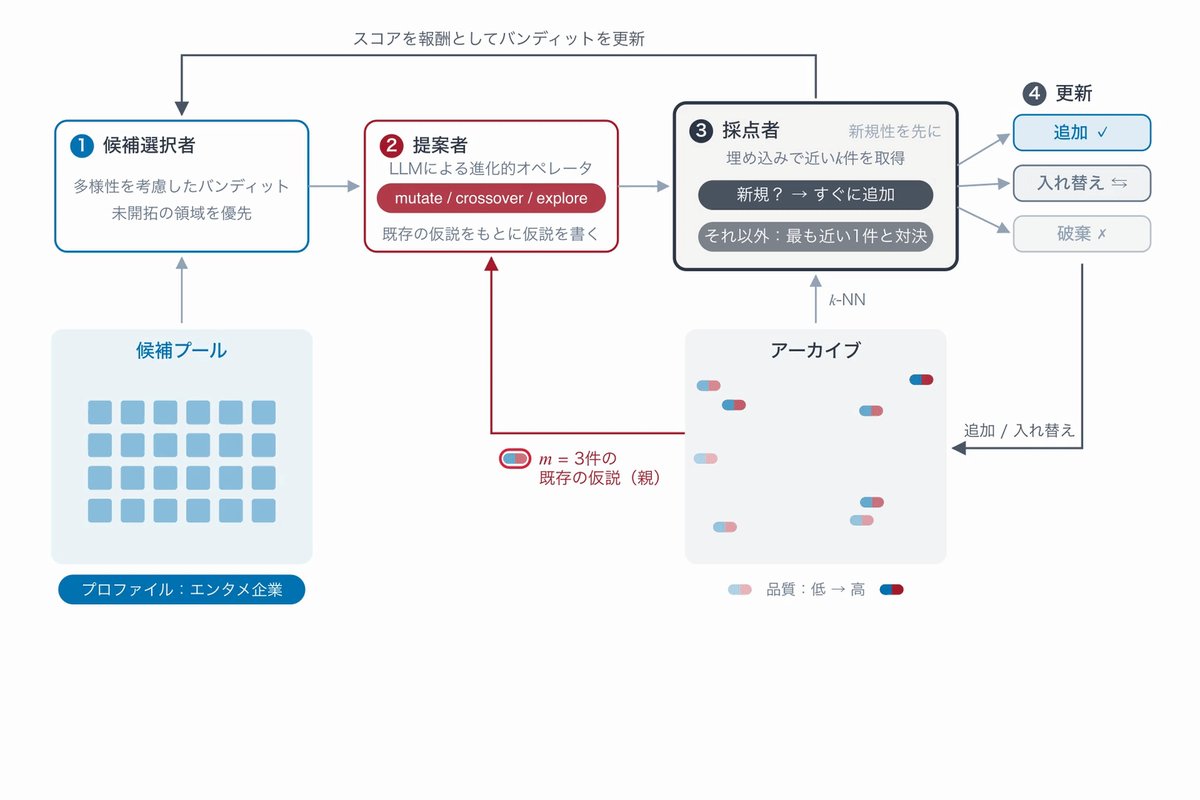
多様な提案を進化させ、意思決定を支える推薦手法「QD-Rec」を開発 ブログ:https://t.co/2AV6dap8Ve 論文:https://t.co/zg1gtm0OlK GitHub:https://t.co/EKNOoEIBEP どの企業を買収候補として検討するか。どの顧客に新しい製品を提案するか。膨大な論文の中から、次に何を読むか。こうした意思 決定では、候補をスコア順に並べるだけでなく、「なぜ選ぶのか」「選んだ先にどのような可能性があるのか」を、異なる観点から比較できることが重要です。 一つの候補にも複数の有望な理由が考えられます。数千件、ときには1万件を超える候補それぞれについて、さまざまな仮説を生成・評価し尽くすには大きなコストがかかります。私たちは、限られた予算の中で「候補」と「仮説」の組を探索し、質が高く多様な提案を見つける問題を「オープンエンドな推薦」として捉えました。 QD-Recは、オープンエンドな探索の研究で発展してきた「Quality-Diversity(QD)」と呼ばれる進化的探索技術を、推薦に応用します。過去の評価結果をもとに次に調べる候補を選び、蓄積された仮説の着眼点をLLMが別の候補に応用したり、複数の仮説を組み合わせたりして、新しい提案を生成します。新しい切り口の提案は残し、似た提案同士ではより優れたものに更新することで、多様な仮説を次の発見の「踏み石」として活かし、推薦の集合を進化させていきます。 実験では、 企業の買収候補探索、架空の顧客プロファイルを使ったターゲティング、研究者向けの論文推薦などで検証しました。同じ評価回数のもとで比較したところ、多くの設定で、比較手法よりもQD-Recの方が評価が高く、より多様で多くの推薦を蓄積できました。 私たちが目指すのは、AIが人間の意思決定を代行することではなく、多様で有望な選択肢と、それらを比較・検討するための判断材料を提供することです。今回の成果を出発点に、QD-Recを次世代の意思決定を支える基盤技術へと発展させていきます。
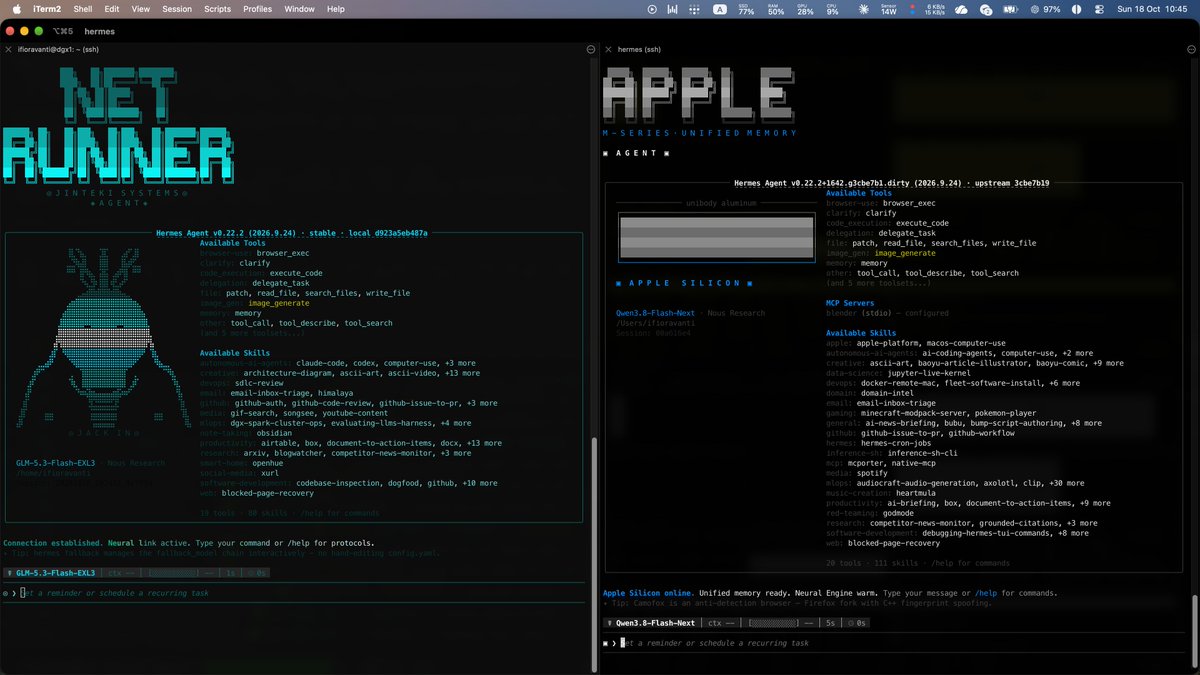
Hermes Agent connected to local models is now installed on ALL my machines to manage everything on them. Main models I'm using are: - GLM 5.3 Flash - Qwen 3.8 Flash Next - DeepSeek V4.1 Flash 1017 Level reached by local models is just AMAZING! Skins repo here: https://t.co/lRtW2i1CBc
Sakana AI won 1st place in the company category at the “Recursive Self Improvement in Mathematics” Hack (OpenMath 2026), held with @stephen_wolfram at Harvard Innovation Labs. Competition: https://t.co/GIe4OW7GYq Results: https://t.co/uTHtSIQVtH Drawing mainly on our Sakana Fugu models and internal agentic tools, our team (Rachel Teo, Abderrahmene Hamdi, Wenyi Wang) contributed 14 mathematical families, including 6 complete resolutions, plus new bounds and structural advances. Thanks to the organizers and everyone involved. We plan to share more about our approach and learnings in a future report.
Your coding agents are fast now. The problem? They can move just as fast in the wrong direction. Miss one update, and they can spend days building the wrong thing - costing you tokens and engineering time. That's why devs are still glued to their monitors. Meet Serro: the Agentic TPM. It keeps your people and coding agents working from the same evolving program. 👇 @serroai