Your curated collection of saved posts and media
I improved NanoGPT Speedrun from 39.9s → 6.7s (-83.2%), more than every record since 2025 combined (-81.4%)! The web is full of rare, repeated content that the LM can’t memorize in time. I solve this with retrieval-augmented n-gram hints🧵 https://t.co/PKQdSpWdxP
We wrote a 37-page technical report on OCRia-1, our SOTA model for document parsing. ✅ It contains comprehensive evals against most other major open-weight OCR models (e.g. Infinity-Parser, LightOnOCR 3, Chandra 2, dots.mocr) on multiple OCR benchmarks: ParseBench, olmOCR-bench, PulseBench-Tab, fr-bench-pdf2md. ✅ It contains detailed visibility into our data and training pipeline, to give a glimpse into how we’re able to curate the right document datasets to push the evaluation metrics within dimensions that matter for doc parsing. ✅ It is blazing fast ⚡️ decoding 2x-4x+ faster than the latest open-weight models. ✅ If you’re building your own vision models, there are 24 pages worth of appendix details (!!) that showcase all of our experimental findings from training to evals! Check it out: https://t.co/DX1bSISNP1 Other links are in our blog! https://t.co/PRxvOFmlVH
We wrote a 37-page technical report on OCRia-1, our SOTA model for document parsing. ✅ It contains comprehensive evals against most other major open-weight OCR models (e.g. Infinity-Parser, LightOnOCR 3, Chandra 2, dots.mocr) on multiple OCR benchmarks: ParseBench, olmOCR-bench, PulseBench-Tab, fr-bench-pdf2md. ✅ It contains detailed visibility into our data and training pipeline, to give a glimpse into how we’re able to curate the right document datasets to push the evaluation metrics within dimensions that matter for doc parsing. ✅ It is blazing fast ⚡️ decoding 2x-4x+ faster than the latest open-weight models. ✅ If you’re building your own vision models, there are 24 pages worth of appendix details (!!) that showcase all of our experimental findings from training to evals! Check it out: https://t.co/DX1bSISNP1 Other links are in our blog! https://t.co/PRxvOFmlVH
Today we’re releasing OCRia-1, a frontier VLM for document parsing that sets a new SOTA in accuracy, cost, and latency. It not only sets a new high score on ParseBench (87.4), but also leads in three 3rd-party benchmarks: olmOCR-bench* (83.5 overall, 92.9 on tables!), PulseBenc

vLLM 🤝 TPU 🚀 Native PyTorch serving on TPUs is here! Built with @Google and @inferact, vLLM-TorchTPU brings familiar PyTorch tools to TPU inference, with prefix caching, speculative decoding, and disaggregated serving. 🛠️ Excited to keep building with the community!
vLLM 🤝 TPU 🚀 Native PyTorch serving on TPUs is here! Built with @Google and @inferact, vLLM-TorchTPU brings familiar PyTorch tools to TPU inference, with prefix caching, speculative decoding, and disaggregated serving. 🛠️ Excited to keep building with the community!
Native PyTorch on TPUs is here—and TorchTPU is officially open source. Train and serve models using the tools you already know: @vllm_project, @sgl_project, @_llm_d_, TorchTitan, @huggingface, and @raydistributed. Learn more from #PyTorchConf2026 → https://t.co/mISCD65vA4 https
llama.cpp b11938 on M2 Pro 32 GiB (using ~3 GiB with the full 128K context) at ~110 t/s with c1 running with Pi! llama serve --hf-repo LiquidAI/LFM3-VL-2B-GGUF:Q4_K_M --host 0.0.0.0 --port 8080 -fa on -np 1 --top-p 1.0 --min-p 0.0 https://t.co/enITzfYaPQ
Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence. > 6 model instances, across text, audio, vision, and omni modalities, generati
Bill Jia (@GoogleCloud) and Zongwei Zhou (@Meta) introduce TorchTPU, a native PyTorch backend for Google TPUs, and agentic developer workflows at #PyTorchCon 2026. TorchTPU is an open source collaboration between Google and Meta, developed in close partnership with PyTorch core maintainers. It integrates with Hugging Face Transformers for modeling, TorchTitan for training, and vLLM and SGLang for serving. They demonstrate how long-horizon agentic workflows can migrate complex model workloads from GPUs to TPUs. They explore using agents for performance optimization, including quantization, custom kernel generation, and advanced sharding strategies. Watch the keynote livestream: https://t.co/6TtaEkvsHz


If you're using LoRA for RL, it's most likely best to deploy your adapter unmerged. Depending on your learning rate, how many effective train steps, etc, you might be losing much of your training updates to rounding to BF16 when you merge the adapter to the base model. https://t.co/xnqBTHVzOW

MacVoice Full voice loop on a MacBook, running on a local LLM - Just talk over the agent to interrupt it. First spoken word of the reply arrives **~0.7 s after you stop talking**. Fits in **1.4 GB**. No PyTorch. Writeup + repo 👇 https://t.co/nfKHKeawK6 https://t.co/UIa6WvXcM2 🔊 Sound on.

In Axolotl, we’ve addressed this with merge-aware LoRA training: we merge the LoRA into the base weights and cast to BF16 inside the forward pass, so the model trains on exactly the weights vLLM serves. Gradients pass straight through the rounding to the LoRA weights, so they keep learning even when a single step is too small to change a BF16 weight. While there are still gaps in this method (support for various distributed parallelisms, ZeRO-3, etc), we hope we can help ensure that you aren't left wondering why what you deployed is underperforming.
🚀 Introducing DeepInfer, our in-house inference framework, now fully open source! Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable. 🔗 https://t.co/JGAik1kgk0 1/4
Hi all, I have a new result I'm excited to share. It turns out that *all existing implementations* of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates "slingshots" when grokking: https://t.co/z6yQeJWad1
how do you fine-tune a decision model on your own data? in these two notebooks, you'll learn: • how to prepare the training data • how to fine-tune our d1-3B decision model • using @UnslothAI and @huggingface TRL all within 30 minutes on a free-tier GPU. unsloth: https://t.co/VxwfzlwHXP TRL: https://t.co/yqzvFwVoZ5 ps: how adorable are these halloween kitties? 👻


Introducing Reinforcement Learning from Collective Rewards (RLCR). RLCR is a recipe that trains language models as agent organisations, which share a message board and workspace. We use it to train Avalon-M1-Mini (120B) and study its behaviour. We find a number of interesting results, including: 🛠️ Learnt organisational hierarchies and divisions of labour 🕵️ Increased collective verification, through hires of verifiers and testers 👥 The rise of collective thinking, where agents think more about other agents and how to help them We believe RLCR can provide a laboratory for studying collective intelligence and multi-agent safety. Blog post and technical report 👇
how do you post-train an agent? we laid it out as a 5-step curriculum, from SFT to RL through a real harness, with livestreams, code and docs for each step https://t.co/qTFRnkkYA7 https://t.co/62R5NqntKp
GPT-6.1 Terra beats Astra in our vision benchmarks wtf OpenAI? had to double-check the results - text - object detection - counting also ~47% faster and ~92% cheaper ↓ leaderboards and examples https://t.co/4AvboaD16g
GPT-6.1 Terra: delivering fast and capable computer use at a lower price. GPT-6.1 Terra understands what’s on screen, takes action across apps, writes naturally, and is a more capable model for your whole workday with the efficiency to take on more of it. https://t.co/8JTN1yonmV

Super interesting result: H-Net learns to dynamically tokenize variable names in coding data as separate tokens, and it scales much better on code compared to BPE
I've always believed that intelligence should come from simple, general building blocks that learn their own abstractions directly from raw data; in other words, the bitter lesson. I think we're finally seeing a real step towards AI that can learn from all data. Language modelin
Muse Spark open weights (even in NVFP4) is an amazing computer use agent I shipped an e2e tutorial on building an env for a browser agent (with OpenEnv, Helium and @huggingface Sandboxes) enjoy 🤗 here's a small visualized run ⤵️ https://t.co/LrgZ3GJmO7
Today we’re releasing ClaimBench, our new benchmark targeted towards decision models. It tests whether a model can tell if a financial document supports, contradicts, or doesn’t address a claim. We evaluated 15 models on 1,960 claims paired with 10-K excerpts, with Decider V1.2 leading the pack of decision models.

We just open-sourced another pair of state-of-the-art Decision Models: pplx-decider-flash-v1.2: 4B params, 1 cent per million tokens (top 4B model on HF Decision Index) pplx-decider-v1.2: 27B params, 2 cents per million tokens (#2 on HF Decision Index overall - for now, will improve rapidly) Both are available on the Perplexity Decisions API as well as in the form of open weights on @huggingface Enjoy!
Our next generation of open weights multimodal decision models comes in two sizes, pplx-decider-v1.2 and pplx-decider-flash-v1.2. Text and vision scores improve. Inference is up to 5x faster: all questions in a request run in one pass. Flash is the top 4B on the Decision Index.
AKV: Cache Engineering for Agents A new serving system that lets LLM agents directly manage their KV cache — dropping unused history and repositioning retained keys without rewriting or re-prefilling. Reduces average cost by 27.7% while improving task accuracy by 1.7 points. https://t.co/AjCQF5MVcT
1/7 🥥 New speculative decoding method! Introducing DCOCO: Contextual Correction of Parallel Drafts. Parallel drafters are fast, but lose context between predicted tokens. DCOCO restores it without giving up parallelism. Up to 6.6× faster than vanilla decoding. 🧵 https://t.co/gdgRcytlxD
Great paper from NVIDIA sharing an open midtraining recipe for agentic coding. NVIDIA kept SFT identical and added one midtraining stage. SWE-bench Multilingual went from 55.8 to 62.8 on Nemotron 3.5 Lightning. The stage sits between pretraining and post-training. It trains at 256K context on 500B tokens of natural software-engineering data, such as packed repositories, pull requests, commit histories and build logs, plus a small share of agent traces. On the same model, SWE-bench Verified rose from 60.7 to 64.5 and SWE-bench Pro from 32.0 to 35.5. On the larger Nemotron 3.5 Super, DeepSWE rose from 11.7 to 15.7. They also explain how they evaluated the recipe. Base-model proxy metrics did not predict post-training results, so every data choice was scored with short fixed SFT runs. If you train coding agents, the recipe and its ablations are published. https://t.co/SJ7JHdd1HY Chat with Paper: https://t.co/eCK8iUNIi0

I put Opus 5.5 and Kimi K3.1 Pro head-to-head with the exact same coding challenge. Build "Lantern Hour" in a single HTML file: 4 art styles, a full day/night cycle, dynamic lighting and shadows, and interactive controls. Canvas 2D only. No libraries or external assets. Which one did better?
Our quadruped HOUND just landed the 🥳cover🥳 of #ScienceRobotics 🐕🦿 @SciRobotics Trained only in sim. One policy. Onboard sensors only🖥️. Trotting, bounding, stairs, gaps, fallen logs: all in the wild.🌳 Paper: https://t.co/0UdKFoFDIU Arxiv: https://t.co/p5aoy76KVO Thread on how we built it 🧵👇 1/N
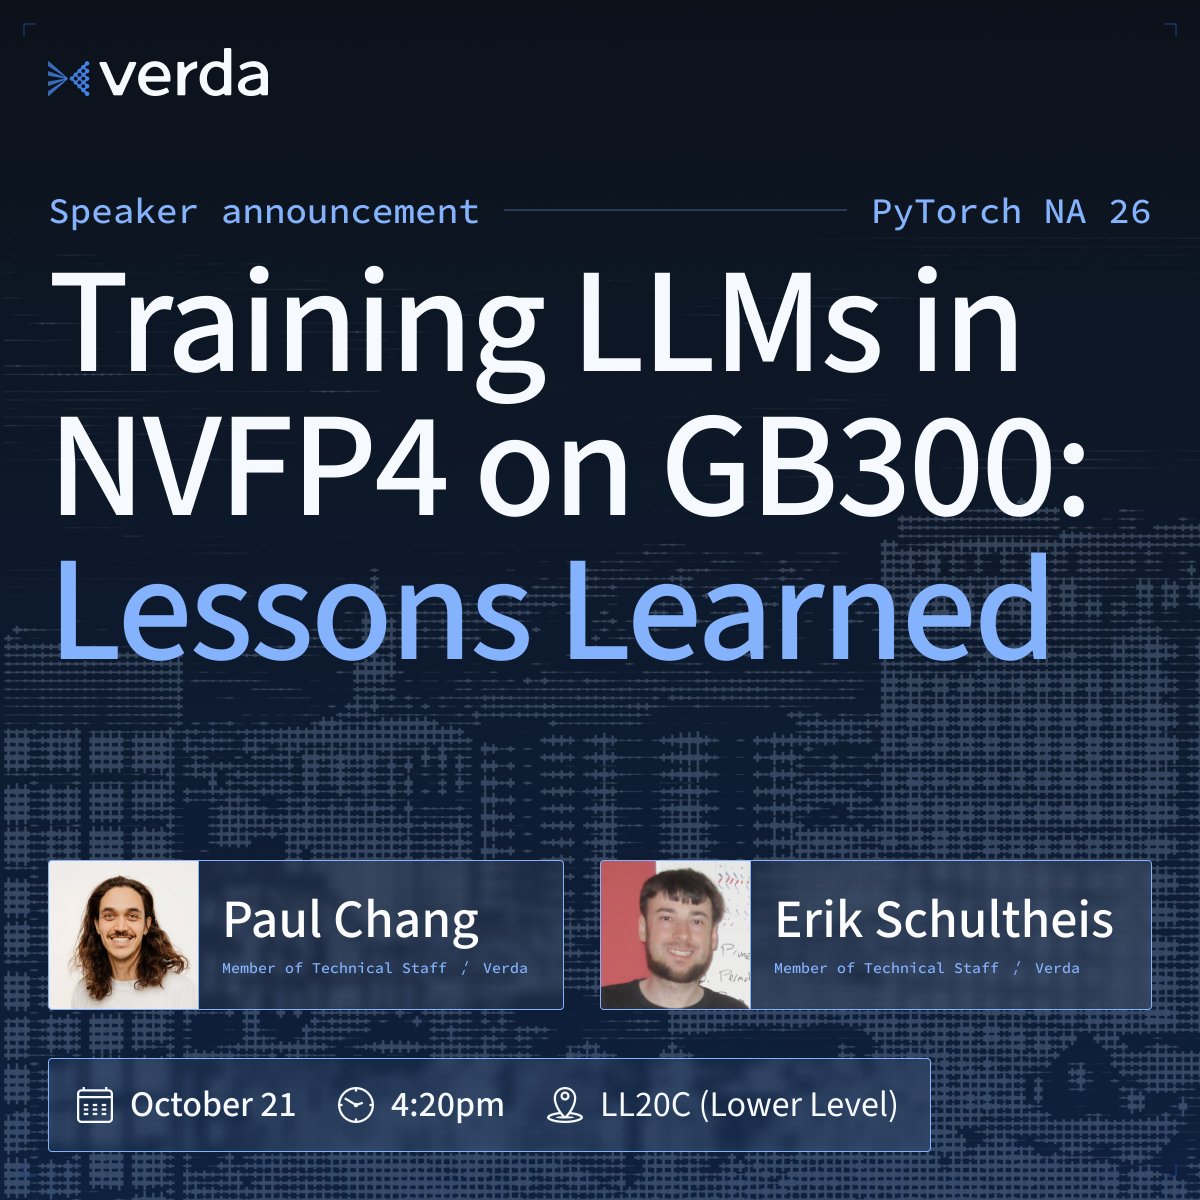
1st talk at @PyTorch: Paul Chang and Erik Schultheis on NVFP4 Training Tips and Tricks, 🗓️ Wed Oct 21 4:20 PM What they learned training dense LLMs on GB300 at 4-bit: hyperparameters, optimisers, and recipes Save it in the calendar: https://t.co/7X4T7LN9zt https://t.co/Gg5PcVb4sA
A steering-first neuron explorer for Qwen3.5-4B, open source on GitHub. Per the creator, a sweep pushes every MLP neuron in a layer up and down on a few prompts and keeps every rollout. The explorer then shows the results as a 3D map of neurons, with a ranked list, per-neuron pages and an embeddings view. Why it matters: seeing what each neuron does to a model's output makes interpretability work easier to inspect and reproduce. https://t.co/k2YKAllyIy Credit: @_lyraaaa_

Inverse IFEval establishes a benchmark for ability to follow out-of-distribution instructions, including inherently flawed questions, code without comments, not using bulleted lists, changing instructions within an interaction, & more. 2/
"In zero-shot settings, preference following accuracy falls below 10% at merely 10 turns (~3k tokens) across most evaluated models. "Even with advanced prompting and retrieval methods, preference following still deteriorates in long-context conversations." 8/
Cool eval. Simply ask an LLM “Land or Water?” and give it a latitude and longitude coordinate as text. Ask 16,200 times, plot as image. The models know. From compressing the internet.
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal. 🔹 Full-project coding: games in Unreal, Unity & Godot. 🔹 Excels at parametric 3D modeling in Blender & CAD. 🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%. 🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks. Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API. Open weights by Nov 4, 2026. 🔗 API: https://t.co/XCrgjXAqMw 🔗 Tech blog: https://t.co/5iPP0MBej6
While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected. Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions. Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent. But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models? We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem. Read the full report: https://t.co/TZSugXi2ZE
