Your curated collection of saved posts and media
We ran @mirendil's new base model on Baseten's private codebases; that is, code it's never seen. Mirendil-Base-Large had the lowest bits per byte (a tokenizer-independent measure of perplexity) of any model we tested. We're excited to be the inference partner to serve Mirendil models. Congrats to the Mirendil team on this launch!

curious people and people interested in llm evals, benchmarks, high data circles, please wake up. my blog post "SWE-bench Multimodal v2 is not multimodal" is up now. https://t.co/Kqd1oOExIn https://t.co/Vd4nPqjiTx
Evals built by @PrimeIntellect residents, fully open: - MazeBench by @patience_cave - PMPP-Hard by @myainotez - PretrainGym by @HuNtEr_J1324 - OpenTTD-Bench by @thesophiaxu [and even more :) ] Super happy to support such amazing work, check it out!
Evals built by @PrimeIntellect residents, fully open: - MazeBench by @patience_cave - PMPP-Hard by @myainotez - PretrainGym by @HuNtEr_J1324 - OpenTTD-Bench by @thesophiaxu [and even more :) ] Super happy to support such amazing work, check it out!
I’m releasing OpenTTD-Bench, a benchmark for measuring frontier LLM agents on real-time, long-horizon tasks, based on a complex business simulation game OpenTTD, where models run competing transportation companies and must make the most amount of profit. https://t.co/DeweIqRgdA
Today we are launching FrontierCS 2, the most frontier benchmark for AI agents in computer science R&D. We built 48 tasks from published papers across 13 areas of CS, refining each one with experts in its field. Excited to co-launch FrontierCS 2 with @kaggle @GoogleDeepMind https://t.co/rfWyJ9tFsf
New research: We developed JOLT, a post-training method where one model acts as both teacher and student, with the teacher trained to give feedback the student can use. On MATH, it matched GRPO's accuracy with 6.5x fewer training tokens. https://t.co/KFHdZ0tuFn https://t.co/Y4Svd9QK4G
We’re working to build the largest collection of private and public practitioner evals. Today, 31 new partners join the Specialized Intelligence Index. Compare open, closed, and specialized models on real work, weigh quality against cost, and see where training could pay off. https://t.co/Ofq6wHNe8w
Plotting ARC-AGI model scores reveals a strong relationship across all three benchmarks. For example, the power curve v2 = v1^4.53 explains about 98% of the variation in ARC-AGI-2 scores. Models tied on ARC-AGI-1 can still differ by over 20 percentage points on ARC-AGI-2. https://t.co/7uG7hNXAwo
Introducing DreamFAR, a world model trained from scratch using only robot data, without internet pretraining. It supports: 🎮 Real-time teleoperation ⏱️ Minutes of long-horizon rollout 🧩 Generalization across 1,000+ tasks https://t.co/A1ifHlj69O 🧵 (1/8) https://t.co/3QtMUFeIkY
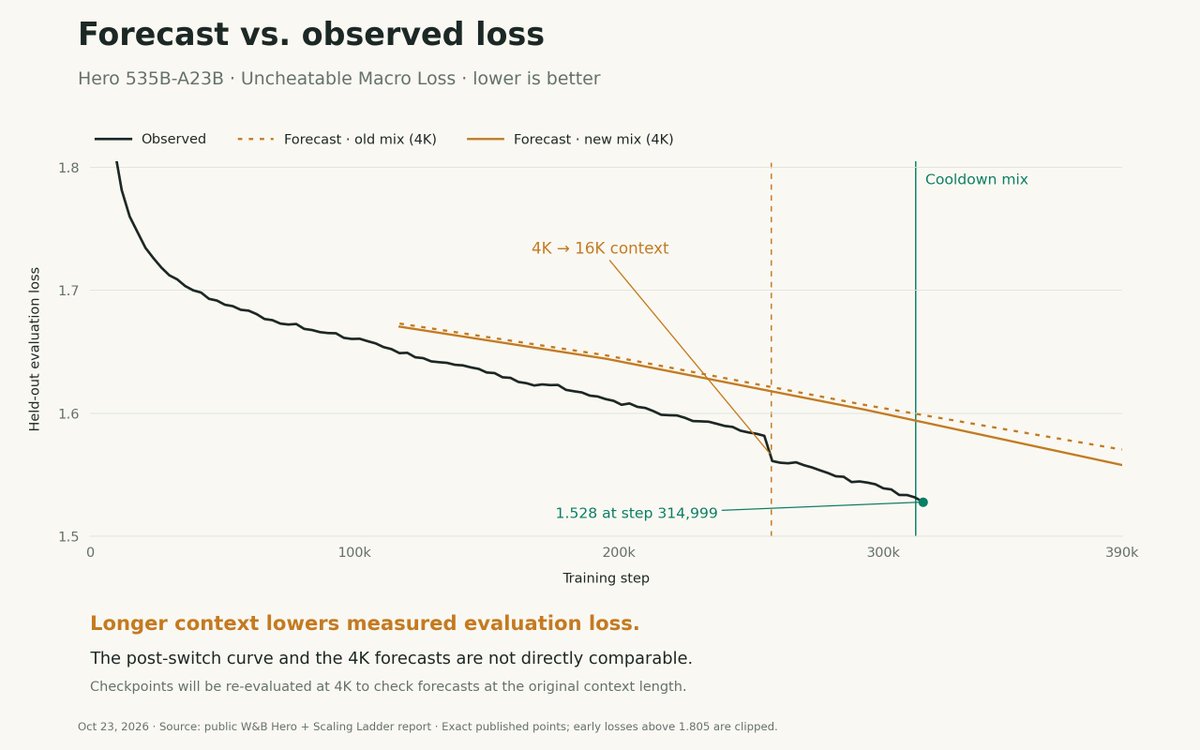
Marin's 535b is now >80% through pretraining! Here’s loss vs. our scaling-ladder forecasts. The sharp drop comes with the 4K→16K context switch, so we're kind of cheating the forecast. (This was planned.) We'll re-eval at 4k too. https://t.co/YPREnmluJY https://t.co/hU9lhL63yx