Your curated collection of saved posts and media
Introducing Drex for Search 🔍 Supercharge your agentic search with Decision-powered retrieval Standard file search holds AI agents back. Drex changes that: • 62% fewer steps to find answers • 56% tokens saved • +4% performance boost across Claude Code, Codex, OpenCode, Hermes, and PI Validated across 6 professional work benchmarks like OfficeQA (529 real-world queries) Upgrade your agentic workflows with the File Search API Try for free: https://t.co/vdEavE1dsd Faster agents. Cheaper runs. Sharper accuracy.
AlphaGo and coding agents need reasoning, so does robotics, which is arguably orders of magnitude harder. But what is the right representation to perform reasoning? Excited to introduce DreamCan, led by @GChongkai ! DreamCan performs sparse visual planning, reasoning over sparse visual frames that are both **reachable** by the robot and **makes progress** towards the task goal, and it can learn this capability from action-free suboptimal videos! Check out Chongkai’s post for more details 🧵⬇️
AlphaGo and coding agents need reasoning, so does robotics, which is arguably orders of magnitude harder. But what is the right representation to perform reasoning? Excited to introduce DreamCan, led by @GChongkai ! DreamCan performs sparse visual planning, reasoning over sparse visual frames that are both **reachable** by the robot and **makes progress** towards the task goal, and it can learn this capability from action-free suboptimal videos! Check out Chongkai’s post for more details 🧵⬇️
🤖Robots need world models for visual planning, but they don't need to imagine every frame. Introducing DreamCan: Sparse Visual Planning for Long-Horizon Robot Manipulation. Project: https://t.co/0yEO3e7XwR Code: https://t.co/qqsP6bYxSg Paper: https://t.co/HALcug4TXb https://t.c
I gave Qwen3.8 27B one prompt and one hour with /goal in Hermes Agent on my RTX 5090, and it built Mont-Saint-Michel (yeah, I'm French) as a voxel diorama. this is the model I run every day. > the tide rises and falls around the mount on a one-minute loop > pilgrims on the causeway, sheep on the salt meadows, gulls overhead > T speeds up the tide, W brings a rain shower, N turns it to night with the windows lit a video shows what a model builds when nobody steers it for an hour. I think it stills need some tweaks and improvements but it is actually very fun to build. reference image in the first comment.
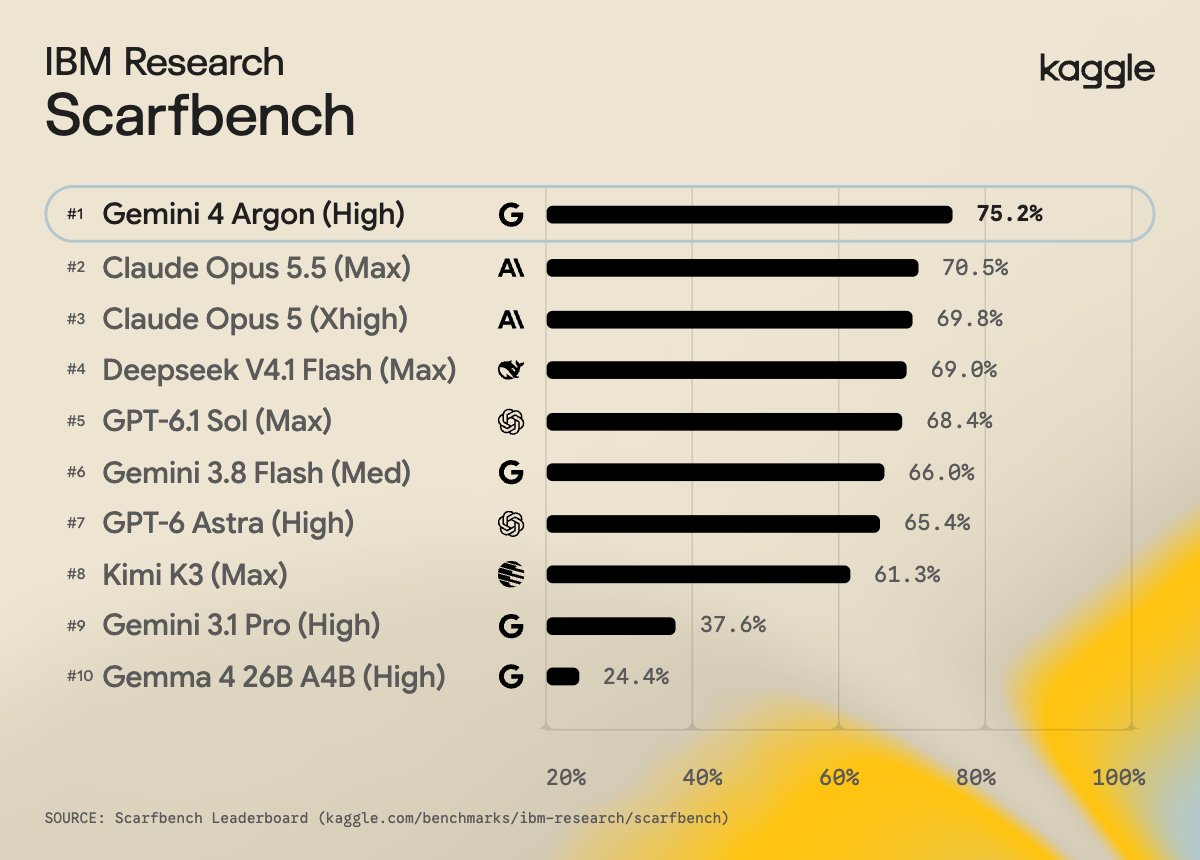
Today, in collaboration with @IBMResearch, we are launching ScarfBench (Self-Contained Application Refactoring Benchmark), an open benchmark designed to test whether coding agents can successfully migrate enterprise Java apps across frameworks like Jakarta EE, Quarkus, and Spring while maintaining the app’s expected behavior. Moving between frameworks takes coordinated changes across dependency injection, persistence, build systems, and deployment infrastructure. An agent can easily generate a migration that looks fine or compiles, only for the app to fail when deployed. ScarfBench puts that to the test. ScarfBench evaluates each model with its harness over 204 migration tasks. Gemini 4 Argon with Antigravity scores 75.2%, followed by Claude Opus 5.5 with Claude Code at 70.5%, and Claude Opus 5 with Claude Code at 69.8%.
Genie 4 brings realistic dynamics and sound to realtime interactive world models! 🧞🚀🎶 This was the last project I worked on at Google 🥲, and the quality and dynamics are still so much better than the 3D creations from the latest frontier models. Bridging this gap to enable accurate, efficient, and high-quality simulations of the real world remains an open research challenge that is key to unlocking useful physical intelligence. Congrats to the whole team, and have fun exploring with Genie 4!
This is Genie 4, our most realistic and interactive world model yet. 🌐 Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.
You can now run pplx-decider-flash-v1.2 locally on your Mac, without an API key. Decider for Mac is an app that runs the 4B decision model on device. Ask a question about text or an image and get a probability back, all on your machine. https://t.co/1BJ4Qv3Urr https://t.co/raBBZ26kbC
Introducing Flora, an open model suite for scaling robotics data engines. It watches robot and human video and annotate what happened (timestamped instructions) and how well it went (rewards and failure reasons). 🔗 https://t.co/yZUS5pHvv9 We use it to train NVIDIA GR00T. 🧵
.@HamelHusain ranked every AI eval method from worst to best. This point stood out to me: You need a human subject matter expert to review your agent's output. Your engineers can't do it (unless you're building an engineering agent). We're all building self-verification into our AI engineering loops. You get AI to prove to itself that what it built works or needs iteration. But there are some things that require judgement or taste from a human. Anything subjective such as marketing materials or GTM strategies.
AI shouldn’t be locked to one hardware vendor or chip. To democratize AI compute, we’ve made MAX source available with Modular 26.7. 🧵