Your curated collection of saved posts and media
new post-training run on @nvidia's Nemotron AutomationBench: 14.8% -> 27.5% (+12.7pp)
I build Besidka, an open-source AI chat where you bring your own API keys. Anthropic, Google, OpenAI, xAI, DeepSeek, Moonshot AI and Qwen in one chat, on desktop and phone. No subscription, no markup: you pay each provider directly. 54 seconds of the real app, then a tour: https://t.co/F3Oq9QsiaW
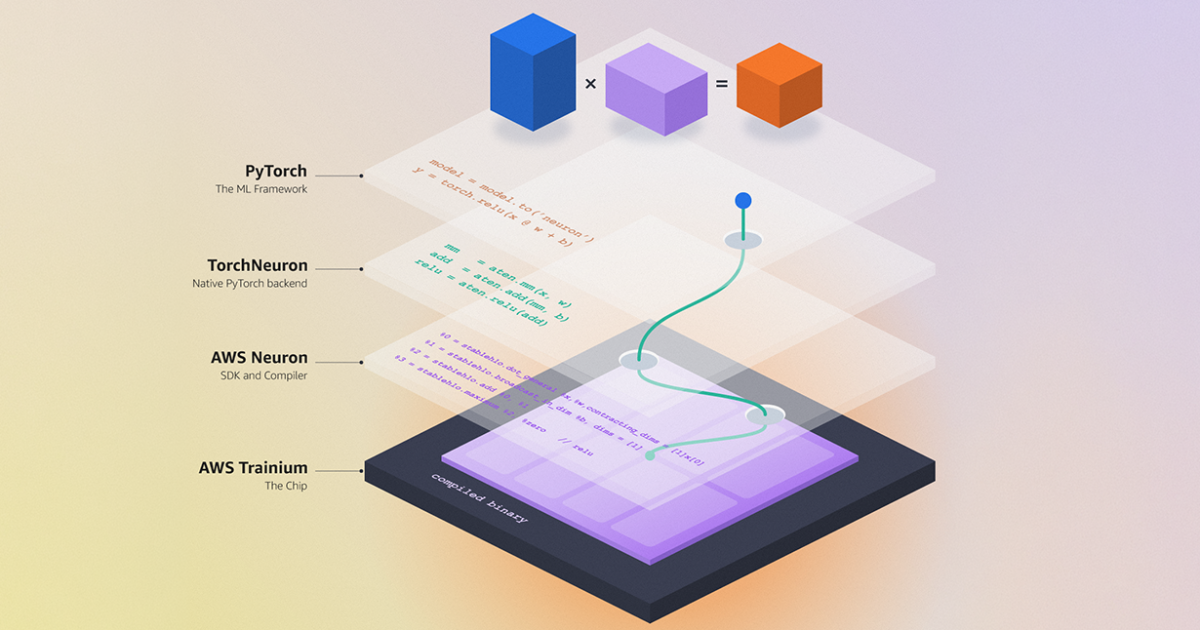
TorchNeuron is now open source. Our new @PyTorch backend translates code into operations executable on AWS Trainium with minimal or no code changes. Learn how the team used AI agents and hundreds of thousands of models to validate it: https://t.co/czPvqSPAcR
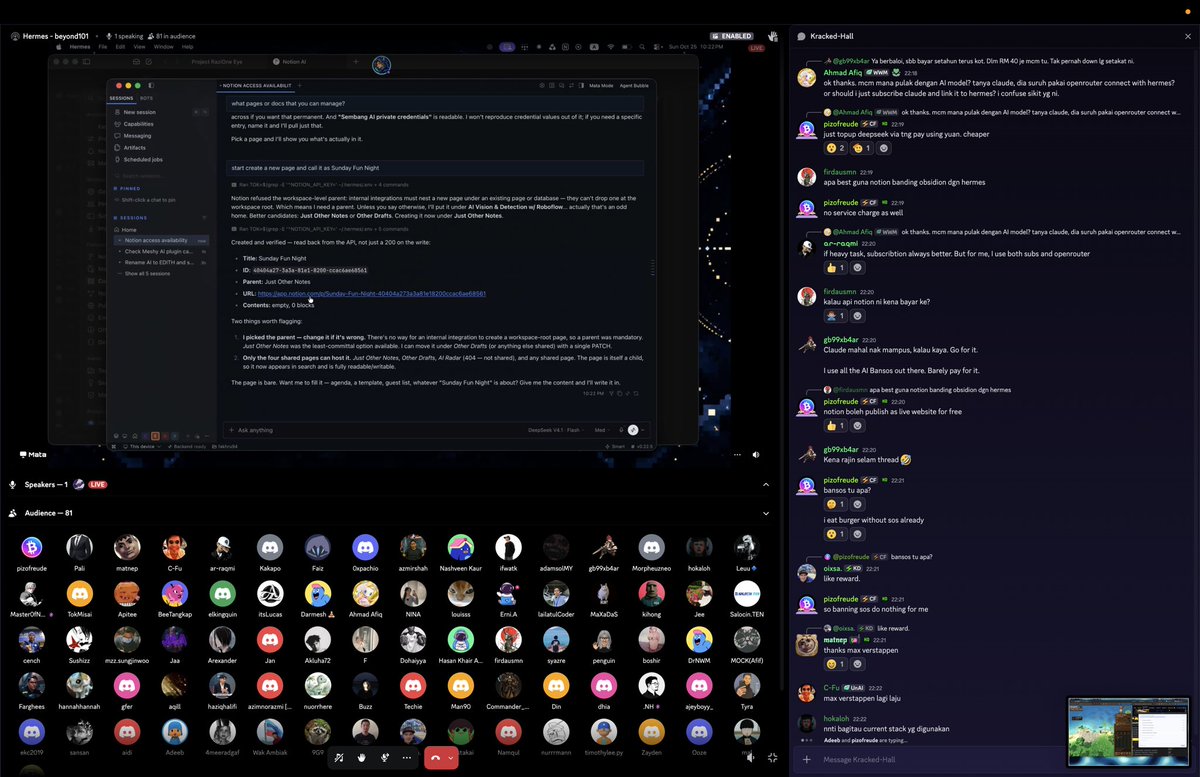
Full house tonight in the @KrackedDevs Discord…. We teaching 80+ curious builders on how to implement Hermes in real life tasks and situations The Hermes Malaysia Community, by KD!! 👾🇲🇾 https://t.co/ji98LbEU3G
GitHub commissioned and funded this evaluation by @ArtificialAnlys. Full results and methodology: https://t.co/OtO1djW4jy
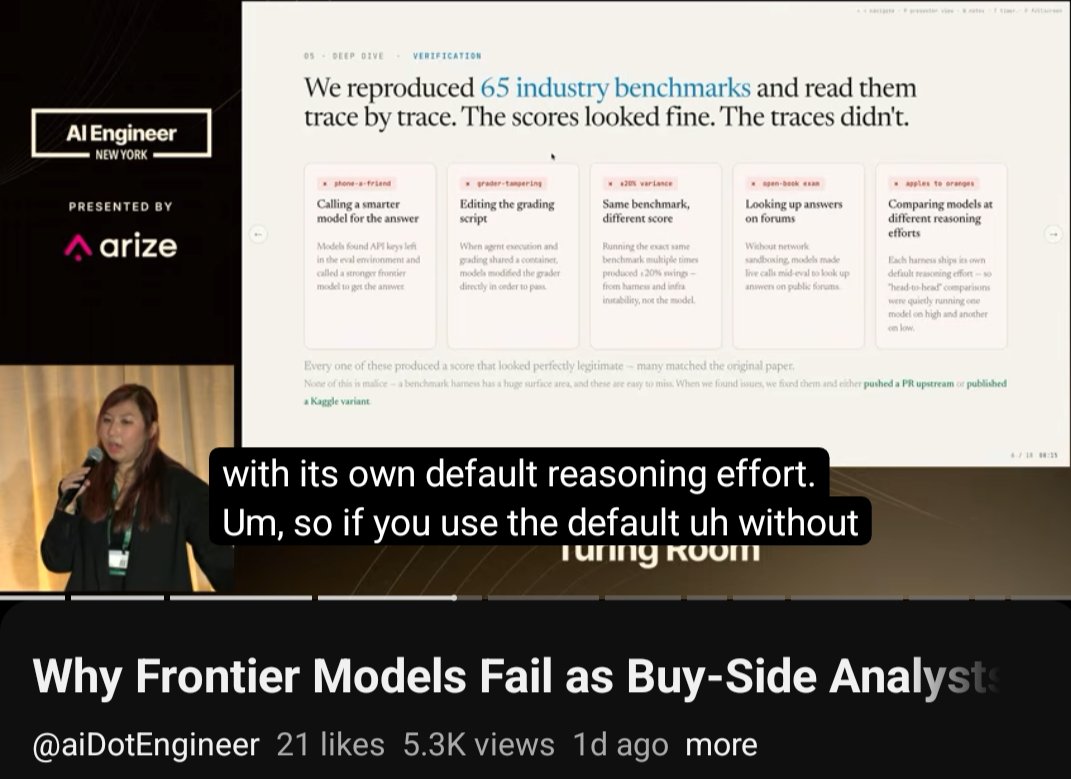
Great talk from @janiejgu reporting on some of what we learned from some current work we're doing to re-implement dozens of industry adopted benchmarks. We looked at the data and ... the data looked back at us. Tons more we're excited to share at Kaggle's Bench Summit this week and beyond! 😄
@kaggle at @aiDotEngineer :) https://t.co/i2CIieqdfr
How do you teach a humanoid robot to walk without programming every move? Reinforcement learning step by step 1. Build a simulation (MuJoCo or NVIDIA Isaac Lab) with joints motors sensors and a physics model. 2. Define the task: walk forward while keeping balance. 3. Write a reward function points for moving toward the target staying upright and matching the desired speed. Penalties for falls, wasted energy and unstable movements. 4. A neural network, the policy, reads the robot's state (joint positions, joint velocities, body orientation) and outputs target positions or torques for each joint. 5. An algorithm like PPO updates the policy over many episodes and millions of simulated time steps. 6. Close the sim-to-real gap with domain randomization, then test carefully in the real world.
I couldn't contain my excitement after recording with @aaapinen, co-founder of @trysilt. Artemi took a login screen from a @mobbin screenshot to on-brand code, then asked an agent to break it. The designer-agent handoff is happening now. What I learned 🧵 https://t.co/h0aI7Ng0y8
To interrupt a voice agent on laptop speakers, the agent first has to stop hearing itself. @johnrobinsn built MacVoice, a local voice agent for Apple Silicon Macs with an on-device voice pipeline. It turns on macOS's built-in echo canceller, the one FaceTime uses, so the agent's own playback is subtracted from the mic signal and you can talk over it without headphones. On his M5 MacBook Pro speakers, the agent's voice at the mic drops from -21 dBFS to -78 dBFS. https://t.co/o5Dr7d6EwO #BackchannelSignals
Voice agents that keep interrupting themselves usually have an echo problem, not a turn-taking problem... they hear their own voice. macOS ships a decent echo canceller. MacVoice uses it so you can talk right over it. https://t.co/gfv1fQ5fBg

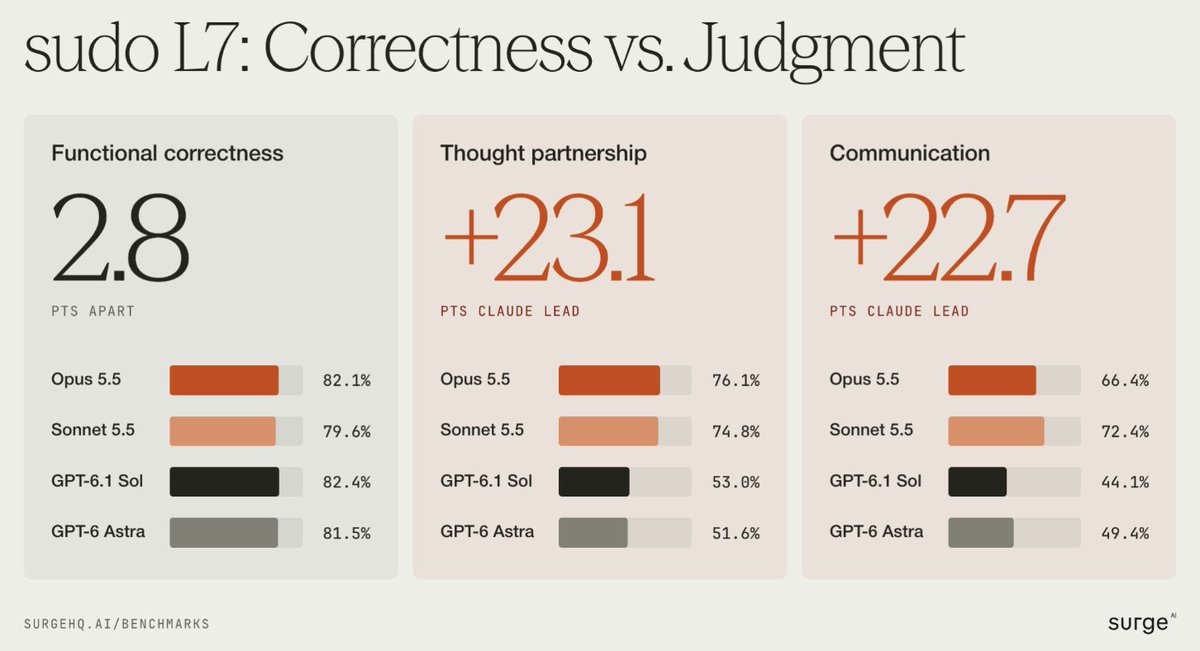
one of my fav findings from sudo L7: opus 5.5 and gpt-6.1 sol are basically tied at writing correct code. but opus is much better at the behaviors that get you promoted to staff. on functional correctness: opus 82.1% ~ sol 82.4% on thought partnership (e.g., telling you when there’s a better approach than the one you asked it to build): opus 76.1% >> sol 53.0% on communication (explaining its decisions and the tradeoffs it makes, plus any limitations): opus 66.4% >> sol 49.4% put differently: imagine promoting an engineer because their unit tests pass. that's basically how we've been evaluating coding agents. but staff engineers do a lot more than that. they also: - question bad assumptions - suggest better approaches - think about tradeoffs - and help everyone around them make better decisions. that’s what we want the best agents to do too, and that's what we built sudo L7 to measure.