Your curated collection of saved posts and media
Introducing FrontierMemory: a new way to evaluate agent memory through downstream task performance. While existing memory benchmarks focus on recall (saturated via agentic search), FrontierMemory focuses on how agents learn from experience.
1/14) Virtual animals are a long-standing goal in neuro-AI, but they should actually behave like real animals. We present SCAMPER: a virtual rat for RL studies that moves naturally during both exploration, and goal-directed behavior. Project page: https://t.co/s0J1igsgEv https://t.co/dLBqhr3ZkA
Synthetic rewrites are now standard to improve data quality and when data is limited. But how much compute should you spend rewriting? And can a model trained on rewrites beat the rewriting model? We fit scaling laws to answer both: 1/🧵 https://t.co/IuYCwIP8G1
Introducing beignet, a new neural field architecture! beignet uses a multiresolution fourier frequency pyramid to achieve faster convergence and higher precision when solving PDEs and finding singularities. Teaser: here is beignet at work fitting an image (super fast)! https://t.co/lv6STiegza
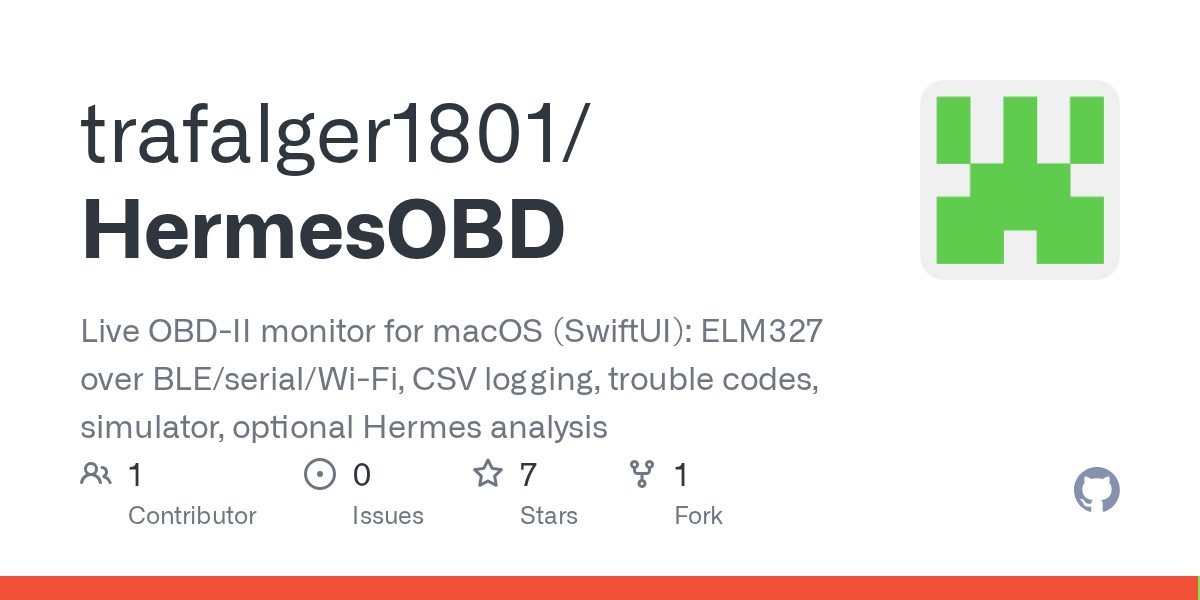
a Hermes Agent user took on a neighbour's 2005 Mustang and asked his agent to build him a Mac app to watch the car live. HermesOBD is the result, a new open-source community build by trafalger1801: a live OBD-II dashboard for macOS that talks to a Bluetooth car adapter and sends the readings to your own Hermes Agent for commentary. - live engine data: RPM, speed, coolant temperature and more - reads stored and pending trouble codes - logs every drive to CSV - sends Hermes a summary every 30 s, and Hermes comments on how the readings change - answers your questions about the data, inside the app - read-only by design: every command goes through an allowlist, no tuning, no reflashing live data and trouble codes are tested on the Mustang with an Innova 3210RS adapter. https://t.co/eaU89ME2uu
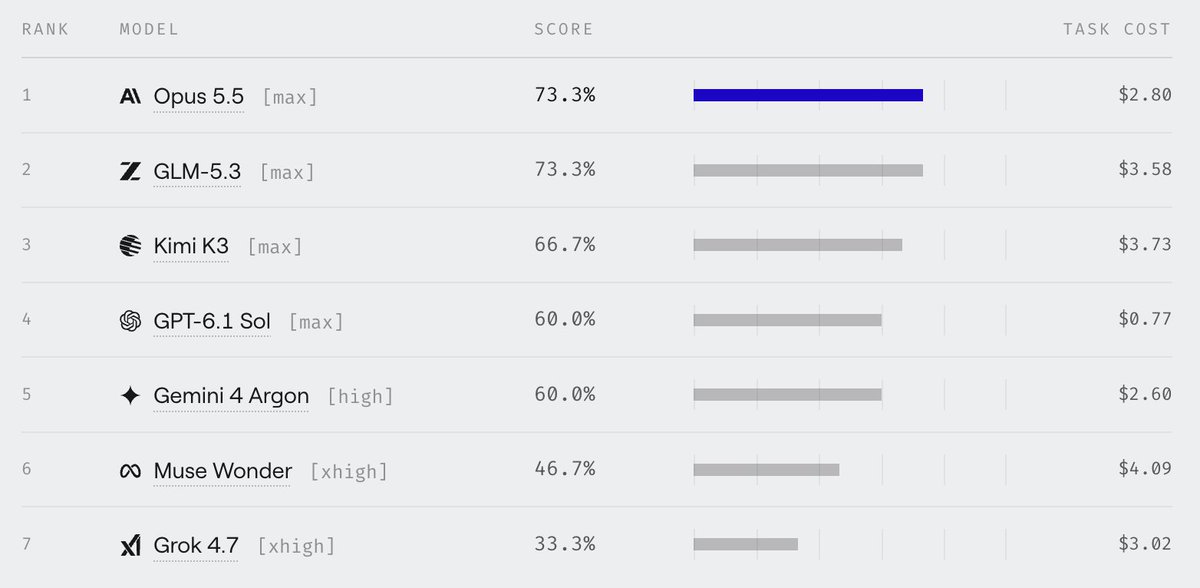
where is claude code with opus 5.5 better for you than codex? specifics please.
Today we’re releasing two decision models, elephant-1 (9B) and mammoth-1 (27B), trained by the @baselabs team, available for free for one week on our Model APIs. mammoth-1 is #1 on the Jev Decision Index and elephant-1 is tied for #1 on the Artificial Analysis Decision Index. It’s a new model, but more importantly, this is an open-source model you can access, deploy, and post-train on Baseten (or wherever you do your best work). The free week ends 10/27/26 at 11:59 PM PT. Try it and let us know what you think. Try mammoth-1 here: https://t.co/x8oDALMuyZ Try elephant-1 here: https://t.co/fmCGb3eGth
Today we are launching @ObsessionDB, the realtime data warehouse for agents. Your agents are hungry for data. Feeding them is getting expensive. Your data warehouse wasn't built (or priced) for that. We learned this the hard way. We scaled our last company to petabytes on ClickHouse and watched the infra bill go vertical. So we built @ObsessionDB . The ClickHouse engine, rebuilt with compute and storage separated, so your infra scales with your agents instead of your bill. 100x faster and 20x cheaper than Snowflake and Databricks. Already live, processing trillions of rows a day. Agents are just getting started...
Won 1st place at the @ycombinator hackathon! 🏆 Most agents don’t have access to a wallet or credit card, so how can they pay for things? To solve this @KonradsKrypto, @muaazshafiq6, and I built D402, a way for agents to do work to pay for things! Instead of requiring a wallet, D402 lets agents complete useful tasks that can be monetized to pay for access, allowing them to get past HTTP 402 paywalls without spending money directly. Every agent has tokens, but not every agent has a wallet. Huge thanks to @nemild for hosting this hackathon! P.S. We are in SF for the week looking to chat with founders. Reach out! 🙌
A step-by-step guide to building a TTS training dataset at the scale of tens of millions of samples. Over the past few months, we've been working on ways to collect and build high-quality TTS training datasets at scale. Compared to collecting text data for LLMs, working with speech data is significantly more complicated, with plenty of engineering challenges along the way. There's surprisingly little public discussion about this, especially when it comes to the practical challenges of collecting speech data at scale. So I wanted to share what we've learned over the past few months: the problems we've run into, the lessons learned, and how we designed and built our data engine from scratch. Hopefully, this will be useful to others working on TTS and large-scale speech datasets. We're also hoping to open-source the full codebase down the road so others can build on it. I also put together a video to make the article easier to follow.