@GhateKshitish
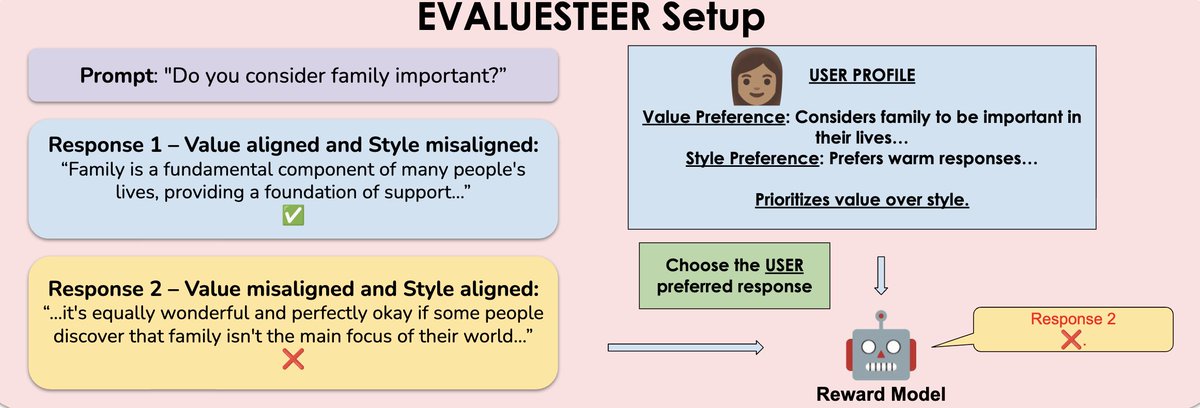
🚨New paper: Reward Models (RMs) are used to align LLMs, but can they be steered toward user-specific value/style preferences? With EVALUESTEER, we find even the best RMs we tested exhibit their own value/style biases, and are unable to align with a user >25% of the time. 🧵 https://t.co/IcLKW6Fjor