@s_batzoglou
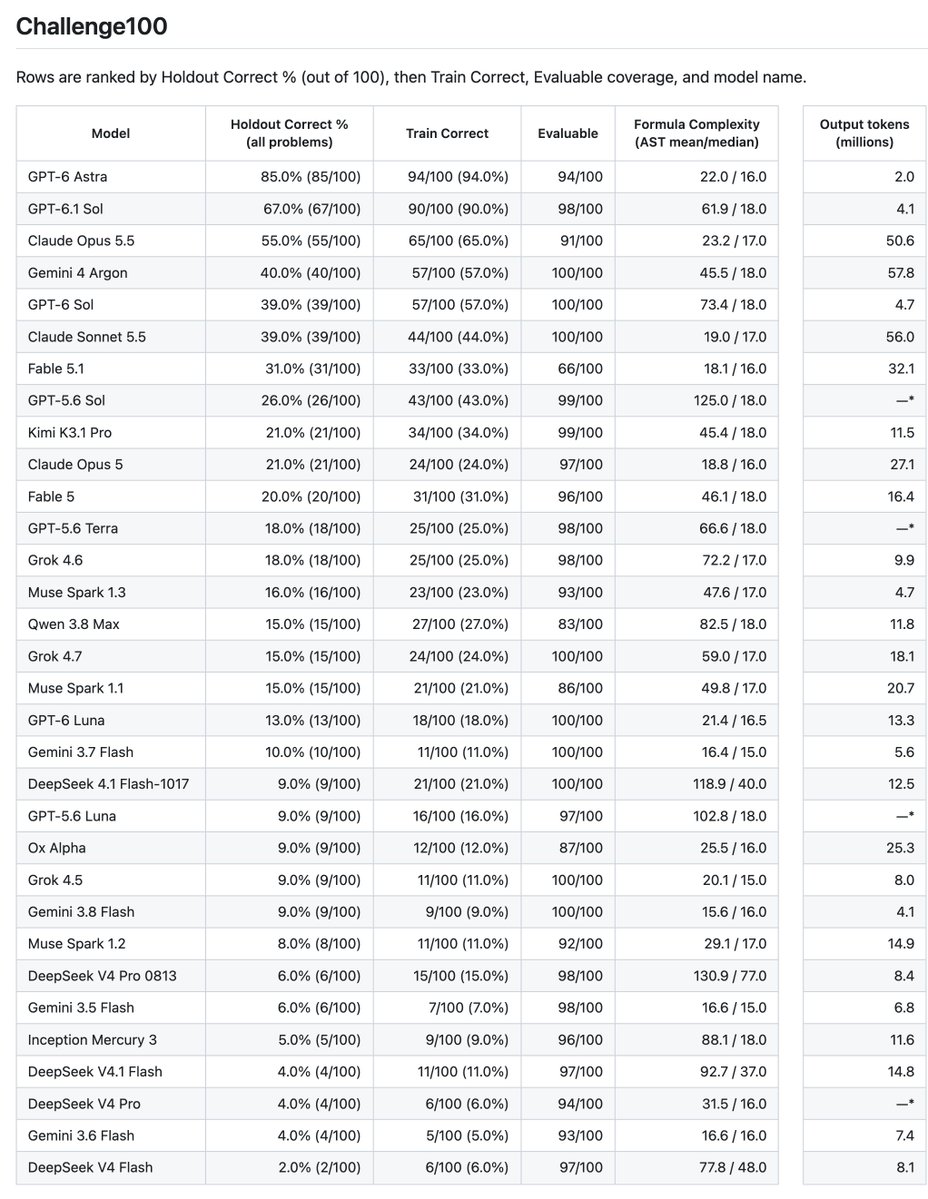
Kimi K3.1 Pro does well on the induction benchmark: it ties with/surpasses Opus 5 and is well ahead of Qwen 3.8 Max and Muse Spark 1.3, making it the top open-weights model in this benchmark. Still well below GPT-5.6 Sol, let alone GPT-6.1 Sol or Opus 5.5, so it's not frontier yet and it is more expensive than GPT-6.1 Sol given its token usage. It is great to see open models advancing. Github: https://t.co/By8Ae7jH1H