@vanstriendaniel
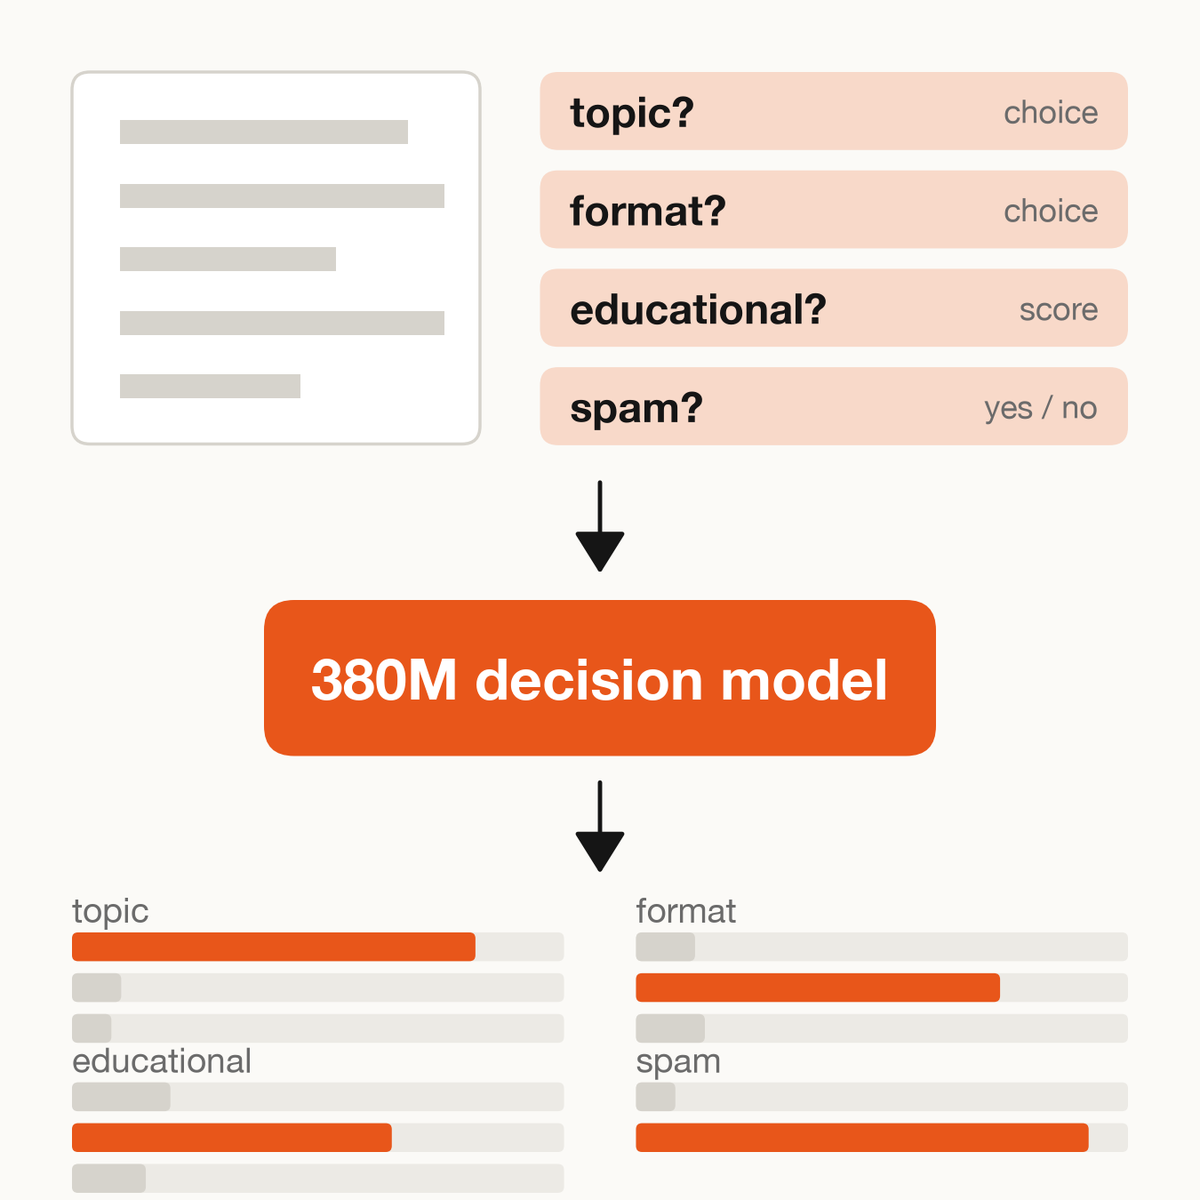
I trained a specialist decision model for curating web-scale data. It's small (380M, fine-tuned from UltraBERT-380M), so it runs relatively cheaply at scale: 1M FineWeb pages took 19 minutes and ~$5 on @huggingface Jobs. It thinks a quarter of those pages are product pages. 6% passed a simple "educational, not spam" filter, and 1 page in 1,020,000 got "outstanding". I've shared the model, the training data (with the source, labeller, and licence for every row), and the full recipe. I hope more people share how they prepare data for training open decision models! We've had some cool open model releases. Time for some more data releases! https://t.co/IdHCqnmnP1