🐦 Twitter Post Details

Viewing enriched Twitter post

@jerryjliu0

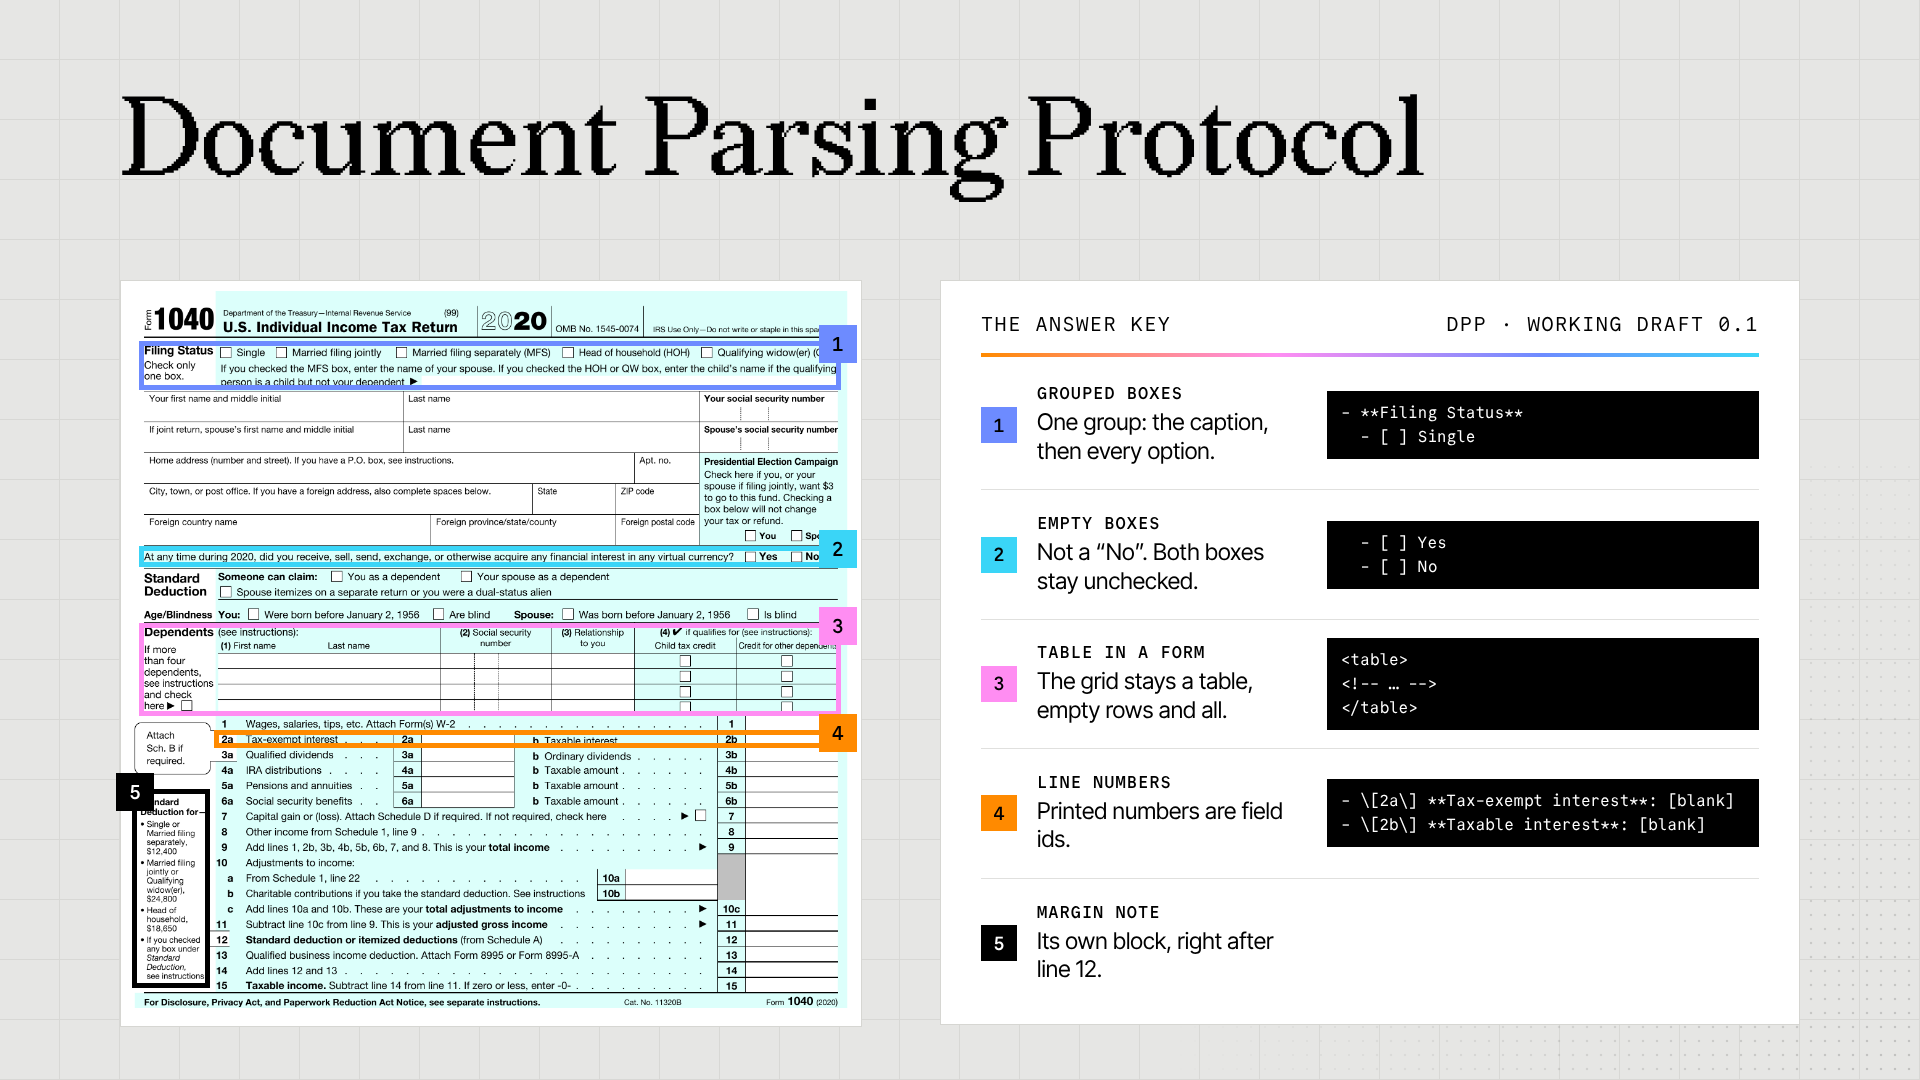
Introducing the Document Parsing Protocol (DPP) There are hundreds of different OCR models and tools, but they might all parse a document in different ways. Some errors are very clear-cut (e.g. hallucinating text, or completely misaligning a table), but many errors are much more ambiguous (e.g. how to represent split tables sharing a header). It's an issue that plagues most parse benchmarks too, because they inherently reward a certain style even if other styles might be semantically correct. We introduce a protocol that proposes a standard way of parsing these documents into a correct format. We've curated a list of 140 rules that cover literally every aspect of doc parsing, for instance: - tables: borderless whitespace tables, header-only tables, horizontal slicing, side-by-side mini tables - forms: key-value regions, checkboxes, checklists, ids and labels, fields outside the form, - charts: standardized chart output, multiple charts, gantt charts, line charts You can use DPP as an evaluation rubric for LLMs when determining the quality of parsing a document. It's not a full evaluation benchmark (yet), but an initial evaluation guide, and meant to encourage a discussion on what are the "best" ways to parse a document. Check it out: https://t.co/HsLh6ma9bB Blog: https://t.co/0md2O2M2Mf

Media 1
Media 2
Media 3

📊 Media Metadata

{
  "media": [
    {
      "url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_0.jpg",
      "media_url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_0.jpg",
      "type": "photo",
      "filename": "media_0.jpg"
    },
    {
      "url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_1.jpg",
      "media_url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_1.jpg",
      "type": "photo",
      "filename": "media_1.jpg"
    },
    {
      "url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_2.jpg",
      "media_url": "https://crmoxkoizveukayfjuyo.supabase.co/storage/v1/object/public/media/posts/2115516581925315034/media_2.jpg",
      "type": "photo",
      "filename": "media_2.jpg"
    }
  ],
  "processed_at": "2026-10-29T00:01:57.630497",
  "pipeline_version": "2.0"
}

🔧 Raw API Response

{
  "type": "tweet",
  "id": "2115516581925315034",
  "url": "https://x.com/jerryjliu0/status/2115516581925315034",
  "twitterUrl": "https://twitter.com/jerryjliu0/status/2115516581925315034",
  "text": "Introducing the Document Parsing Protocol (DPP) \n\nThere are hundreds of different OCR models and tools, but they might all parse a document in different ways. \n\nSome errors are very clear-cut (e.g. hallucinating text, or completely misaligning a table), but many errors are much more ambiguous (e.g. how to represent split tables sharing a header). It's an issue that plagues most parse benchmarks too, because they inherently reward a certain style even if other styles might be semantically correct. \n\nWe introduce a protocol that proposes a standard way of parsing these documents into a correct format. We've curated a list of 140 rules that cover literally every aspect of doc parsing, for instance:\n- tables: borderless whitespace tables, header-only tables, horizontal slicing, side-by-side mini tables\n- forms: key-value regions, checkboxes, checklists, ids and labels, fields outside the form, \n- charts: standardized chart output, multiple charts, gantt charts, line charts\n\nYou can use DPP as an evaluation rubric for LLMs when determining the quality of parsing a document. \n\nIt's not a full evaluation benchmark (yet), but an initial evaluation guide, and meant to encourage a discussion on what are the \"best\" ways to parse a document.\n\nCheck it out: https://t.co/HsLh6ma9bB\n\nBlog: https://t.co/0md2O2M2Mf",
  "source": "",
  "retweetCount": 27,
  "replyCount": 40,
  "likeCount": 305,
  "quoteCount": 4,
  "viewCount": 12758,
  "createdAt": "Wed Oct 28 18:50:32 +0000 2026",
  "lang": "en",
  "bookmarkCount": 362,
  "isReply": false,
  "inReplyToId": null,
  "conversationId": "2115516581925315034",
  "displayTextRange": [
    0,
    278
  ],
  "inReplyToUserId": null,
  "inReplyToUsername": null,
  "author": {
    "type": "user",
    "userName": "jerryjliu0",
    "url": "https://x.com/jerryjliu0",
    "twitterUrl": "https://twitter.com/jerryjliu0",
    "id": "369777416",
    "name": "Jerry Liu",
    "isVerified": false,
    "isBlueVerified": true,
    "verifiedType": null,
    "profilePicture": "https://pbs.twimg.com/profile_images/1283610285031460864/1Q4zYhtb_normal.jpg",
    "coverPicture": "",
    "description": "",
    "location": "",
    "followers": 87089,
    "following": 1628,
    "status": "",
    "canDm": true,
    "canMediaTag": true,
    "createdAt": "Wed Sep 07 22:54:31 +0000 2011",
    "entities": {
      "description": {
        "urls": []
      },
      "url": {}
    },
    "fastFollowersCount": 0,
    "favouritesCount": 11085,
    "hasCustomTimelines": true,
    "isTranslator": false,
    "mediaCount": 1724,
    "statusesCount": 7966,
    "withheldInCountries": [],
    "affiliatesHighlightedLabel": {
      "label": {
        "badge": {
          "url": "https://pbs.twimg.com/profile_images/1967920417760251904/0ytfduMQ_bigger.png"
        },
        "description": "LlamaIndex 🦙",
        "url": {
          "url": "https://twitter.com/llama_index",
          "url_type": "DeepLink"
        },
        "user_label_display_type": "Badge",
        "user_label_type": "BusinessLabel"
      }
    },
    "possiblySensitive": false,
    "pinnedTweetIds": [
      "2107864677611139096"
    ],
    "profile_bio": {
      "description": "Parsing the world's hardest PDFs @llama_index. cofounder/CEO\n\nLlamaParse: https://t.co/XYZmx5TFz8\nEnterprise: https://t.co/Ht5jwxSrQB",
      "entities": {
        "description": {
          "urls": [
            {
              "display_url": "cloud.llamaindex.ai",
              "expanded_url": "https://cloud.llamaindex.ai/",
              "indices": [
                74,
                97
              ],
              "url": "https://t.co/XYZmx5TFz8"
            },
            {
              "display_url": "llamaindex.ai/contact",
              "expanded_url": "https://www.llamaindex.ai/contact",
              "indices": [
                110,
                133
              ],
              "url": "https://t.co/Ht5jwxSrQB"
            }
          ],
          "user_mentions": [
            {
              "id_str": "",
              "indices": [
                33,
                45
              ],
              "name": "",
              "screen_name": "llama_index"
            }
          ]
        },
        "url": {
          "urls": [
            {
              "display_url": "llamaindex.ai",
              "expanded_url": "https://www.llamaindex.ai/",
              "indices": [
                0,
                23
              ],
              "url": "https://t.co/YiIfjVlzb6"
            }
          ]
        }
      }
    },
    "isAutomated": false,
    "automatedBy": null,
    "protected": false
  },
  "extendedEntities": {
    "media": [
      {
        "display_url": "pic.x.com/pCWBo2HmBF",
        "expanded_url": "https://x.com/jerryjliu0/status/2115516581925315034/photo/1",
        "ext_master_playlist_only": [],
        "ext_media_availability": {
          "status": "Available"
        },
        "ext_playlists": [],
        "features": {
          "large": {
            "faces": []
          },
          "orig": {
            "faces": []
          }
        },
        "id_str": "2115514459091566592",
        "indices": [
          279,
          302
        ],
        "media_key": "3_2115514459091566592",
        "media_results": {
          "id": "QXBpTWVkaWFSZXN1bHRzOgwAAQoAAR1b0TErWwAACgACHVvTH24bYdoAAA==",
          "result": {
            "__typename": "ApiMedia",
            "id": "QXBpTWVkaWE6DAABCgABHVvRMStbAAAKAAIdW9Mfbhth2gAA",
            "media_key": "3_2115514459091566592"
          }
        },
        "media_url_https": "https://pbs.twimg.com/media/HVvRMStbAAAy4UD.jpg",
        "original_info": {
          "focus_rects": [
            {
              "h": 381,
              "w": 680,
              "x": 0,
              "y": 0
            },
            {
              "h": 383,
              "w": 383,
              "x": 234,
              "y": 0
            },
            {
              "h": 383,
              "w": 336,
              "x": 257,
              "y": 0
            },
            {
              "h": 383,
              "w": 192,
              "x": 329,
              "y": 0
            },
            {
              "h": 383,
              "w": 680,
              "x": 0,
              "y": 0
            }
          ],
          "height": 383,
          "width": 680
        },
        "sizes": {
          "large": {
            "h": 383,
            "w": 680
          }
        },
        "type": "photo",
        "url": "https://t.co/pCWBo2HmBF"
      }
    ]
  },
  "card": null,
  "place": {},
  "entities": {
    "hashtags": [],
    "symbols": [],
    "urls": [
      {
        "display_url": "parseprotocol.com/guide/forms-fo…",
        "expanded_url": "https://www.parseprotocol.com/guide/forms-forms-and-key-value-regions",
        "indices": [
          1265,
          1288
        ],
        "url": "https://t.co/HsLh6ma9bB"
      },
      {
        "display_url": "llamaindex.ai/blog/introduci…",
        "expanded_url": "https://www.llamaindex.ai/blog/introducing-the-document-parsing-protocol",
        "indices": [
          1296,
          1319
        ],
        "url": "https://t.co/0md2O2M2Mf"
      }
    ],
    "user_mentions": []
  },
  "quoted_tweet": {
    "type": "tweet",
    "id": "2115466450534097158",
    "url": "https://x.com/llama_index/status/2115466450534097158",
    "twitterUrl": "https://twitter.com/llama_index/status/2115466450534097158",
    "text": "Is that a table, or just text that happens to line up?\nIf a table has two header rows, should the output preserve both?\n\nParsers make these judgment calls differently. Those differences shape what your agent understands about a document.\n\nWe built the Document Parsing Protocol (DPP) to give those decisions a shared rulebook.\n\nDPP covers text, tables, forms, charts, and diagrams, and even includes chemical structures and music notation. Each rule comes with example pages and expected outputs to make it concrete.\n\nThe working draft is live, and we’d love your feedback :) Get the Claude skill or ChatGPT reference file, try it on your messiest page, and let us know what comes back.\n\nTry it here: https://t.co/i3vtFTzZtX\n\nRead more: https://t.co/iSI8zqjpzP",
    "source": "",
    "retweetCount": 9,
    "replyCount": 8,
    "likeCount": 51,
    "quoteCount": 4,
    "viewCount": 16471,
    "createdAt": "Wed Oct 28 15:31:19 +0000 2026",
    "lang": "en",
    "bookmarkCount": 52,
    "isReply": false,
    "inReplyToId": null,
    "conversationId": "2115466450534097158",
    "displayTextRange": [
      0,
      277
    ],
    "inReplyToUserId": null,
    "inReplyToUsername": null,
    "author": {
      "type": "user",
      "userName": "llama_index",
      "url": "https://x.com/llama_index",
      "twitterUrl": "https://twitter.com/llama_index",
      "id": "1604278358296055808",
      "name": "LlamaIndex 🦙",
      "isVerified": false,
      "isBlueVerified": true,
      "verifiedType": "Business",
      "profilePicture": "https://pbs.twimg.com/profile_images/1967920417760251904/0ytfduMQ_normal.png",
      "coverPicture": "https://pbs.twimg.com/profile_banners/1604278358296055808/1776721175",
      "description": "",
      "location": "",
      "followers": 122014,
      "following": 39,
      "status": "",
      "canDm": false,
      "canMediaTag": true,
      "createdAt": "Sun Dec 18 00:52:44 +0000 2022",
      "entities": {
        "description": {
          "urls": []
        },
        "url": {}
      },
      "fastFollowersCount": 0,
      "favouritesCount": 1680,
      "hasCustomTimelines": true,
      "isTranslator": false,
      "mediaCount": 1997,
      "statusesCount": 4088,
      "withheldInCountries": [],
      "affiliatesHighlightedLabel": {},
      "possiblySensitive": false,
      "pinnedTweetIds": [],
      "profile_bio": {
        "description": "Turn any doc into AI-ready context. The AI research lab for document parsing and extraction. Developer-first APIs.\n\nLlamaParse: https://t.co/yQGTiRSfFL",
        "entities": {
          "description": {
            "urls": [
              {
                "display_url": "cloud.llamaindex.ai",
                "expanded_url": "https://cloud.llamaindex.ai/",
                "indices": [
                  128,
                  151
                ],
                "url": "https://t.co/yQGTiRSfFL"
              }
            ]
          },
          "url": {
            "urls": [
              {
                "display_url": "llamaindex.ai",
                "expanded_url": "https://www.llamaindex.ai/",
                "indices": [
                  0,
                  23
                ],
                "url": "https://t.co/epzefqPT9Z"
              }
            ]
          }
        }
      },
      "isAutomated": false,
      "automatedBy": null,
      "protected": false
    },
    "extendedEntities": {
      "media": [
        {
          "display_url": "pic.x.com/udsbuWwlvD",
          "expanded_url": "https://x.com/llama_index/status/2115466450534097158/photo/1",
          "ext_master_playlist_only": [],
          "ext_media_availability": {
            "status": "Available"
          },
          "ext_playlists": [],
          "features": {
            "large": {
              "faces": [
                {
                  "h": 88,
                  "w": 88,
                  "x": 1785,
                  "y": 442
                }
              ]
            },
            "orig": {
              "faces": [
                {
                  "h": 88,
                  "w": 88,
                  "x": 1785,
                  "y": 442
                }
              ]
            }
          },
          "id_str": "2115466447044444160",
          "indices": [
            278,
            301
          ],
          "media_key": "3_2115466447044444160",
          "media_results": {
            "id": "QXBpTWVkaWFSZXN1bHRzOgwAAQoAAR1bpYZ+V4AACgACHVulh05XYQYAAA==",
            "result": {
              "__typename": "ApiMedia",
              "id": "QXBpTWVkaWE6DAABCgABHVulhn5XgAAKAAIdW6WHTldhBgAA",
              "media_key": "3_2115466447044444160"
            }
          },
          "media_url_https": "https://pbs.twimg.com/media/HVulhn5XgAAI0Uj.jpg",
          "original_info": {
            "focus_rects": [
              {
                "h": 1075,
                "w": 1920,
                "x": 0,
                "y": 0
              },
              {
                "h": 1080,
                "w": 1080,
                "x": 660,
                "y": 0
              },
              {
                "h": 1080,
                "w": 947,
                "x": 727,
                "y": 0
              },
              {
                "h": 1080,
                "w": 540,
                "x": 930,
                "y": 0
              },
              {
                "h": 1080,
                "w": 1920,
                "x": 0,
                "y": 0
              }
            ],
            "height": 1080,
            "width": 1920
          },
          "sizes": {
            "large": {
              "h": 1080,
              "w": 1920
            }
          },
          "type": "photo",
          "url": "https://t.co/udsbuWwlvD"
        }
      ]
    },
    "card": null,
    "place": {},
    "entities": {
      "hashtags": [],
      "symbols": [],
      "urls": [
        {
          "display_url": "parseprotocol.com/#adopt",
          "expanded_url": "https://www.parseprotocol.com/#adopt",
          "indices": [
            701,
            724
          ],
          "url": "https://t.co/i3vtFTzZtX"
        },
        {
          "display_url": "llamaindex.ai/blog/introduci…",
          "expanded_url": "https://www.llamaindex.ai/blog/introducing-the-document-parsing-protocol",
          "indices": [
            737,
            760
          ],
          "url": "https://t.co/iSI8zqjpzP"
        }
      ],
      "user_mentions": []
    },
    "quoted_tweet": null,
    "retweeted_tweet": null,
    "isLimitedReply": false,
    "communityInfo": null,
    "article": null
  },
  "retweeted_tweet": null,
  "isLimitedReply": false,
  "communityInfo": null,
  "article": null
}