@random_walker
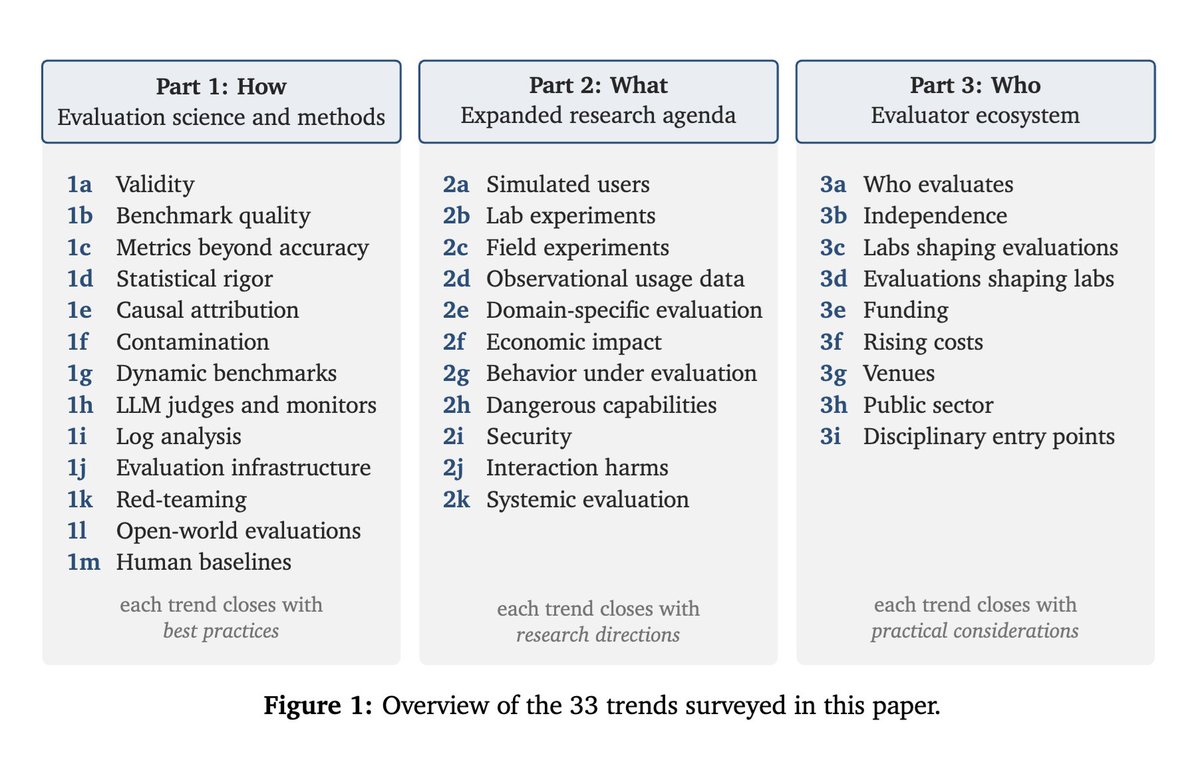
Resharing our paper on the science of AI agent evaluation because the PHP vulnerability happened right as we announced the paper last week and our server was taken down all day to upgrade PHP 🫠 PDF: https://t.co/8m13p9d70F Webpage: https://t.co/xGAvBCGW4a Blog: https://t.co/qxO21qWZfm There are growing calls for independent and embedded AI evaluation, especially of AI agents. But much remains unclear: what constitutes a “good” evaluation, what needs to be evaluated in the first place, and how best to coordinate and support the influx of people entering the burgeoning evaluation ecosystem. Our group at Princeton has been working to improve the state of AI agent evaluation for about three years. We teamed up with people who’ve done foundational work on evaluation at Stanford, the UK AI Security Institute, and Brookings. Our paper is titled Emerging Trends in AI Agent Evaluation. We synthesized the trends we see across three dimensions—the science and methods, the research agenda, and the evaluation ecosystem—with the goal to help those who are upskilling for this new paradigm. We also aim to equip evaluators, funders, and the public with a set of questions to ask, and provide actionable recommendations. By @flxcn, @steverab, @PKirgis, @nityndg, @RishiBommasani, @DubMagda, @CUdudec, @AnkaReuel, Elham Tabassi, @sayashk, and me.