@echen
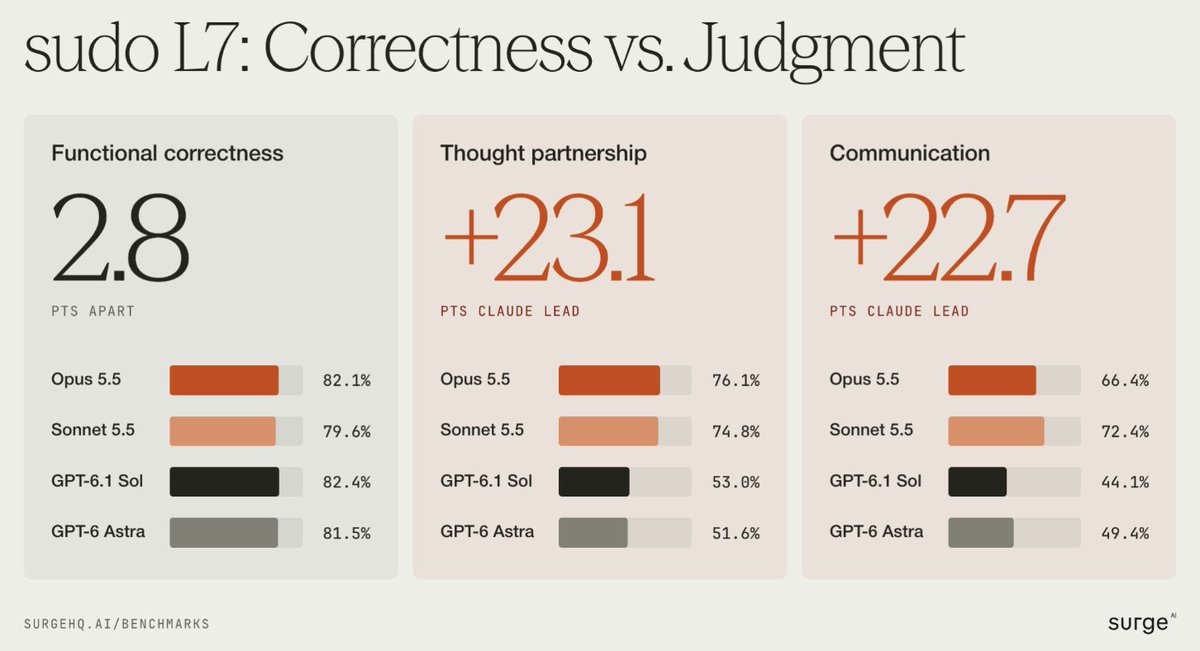
one of my fav findings from sudo L7: opus 5.5 and gpt-6.1 sol are basically tied at writing correct code. but opus is much better at the behaviors that get you promoted to staff. on functional correctness: opus 82.1% ~ sol 82.4% on thought partnership (e.g., telling you when there’s a better approach than the one you asked it to build): opus 76.1% >> sol 53.0% on communication (explaining its decisions and the tradeoffs it makes, plus any limitations): opus 66.4% >> sol 49.4% put differently: imagine promoting an engineer because their unit tests pass. that's basically how we've been evaluating coding agents. but staff engineers do a lot more than that. they also: - question bad assumptions - suggest better approaches - think about tradeoffs - and help everyone around them make better decisions. that’s what we want the best agents to do too, and that's what we built sudo L7 to measure.